I Took Laya's "Calibrated RL" Apart. It's Cross-Entropy With Extra Steps.
Laya's README reports a raw ECE of 0.466 on the typed-decisions benchmark before temperature scaling.

Sep 26, 2026
5 min
Laya's README reports a raw ECE of 0.466 on the typed-decisions benchmark before temperature scaling.
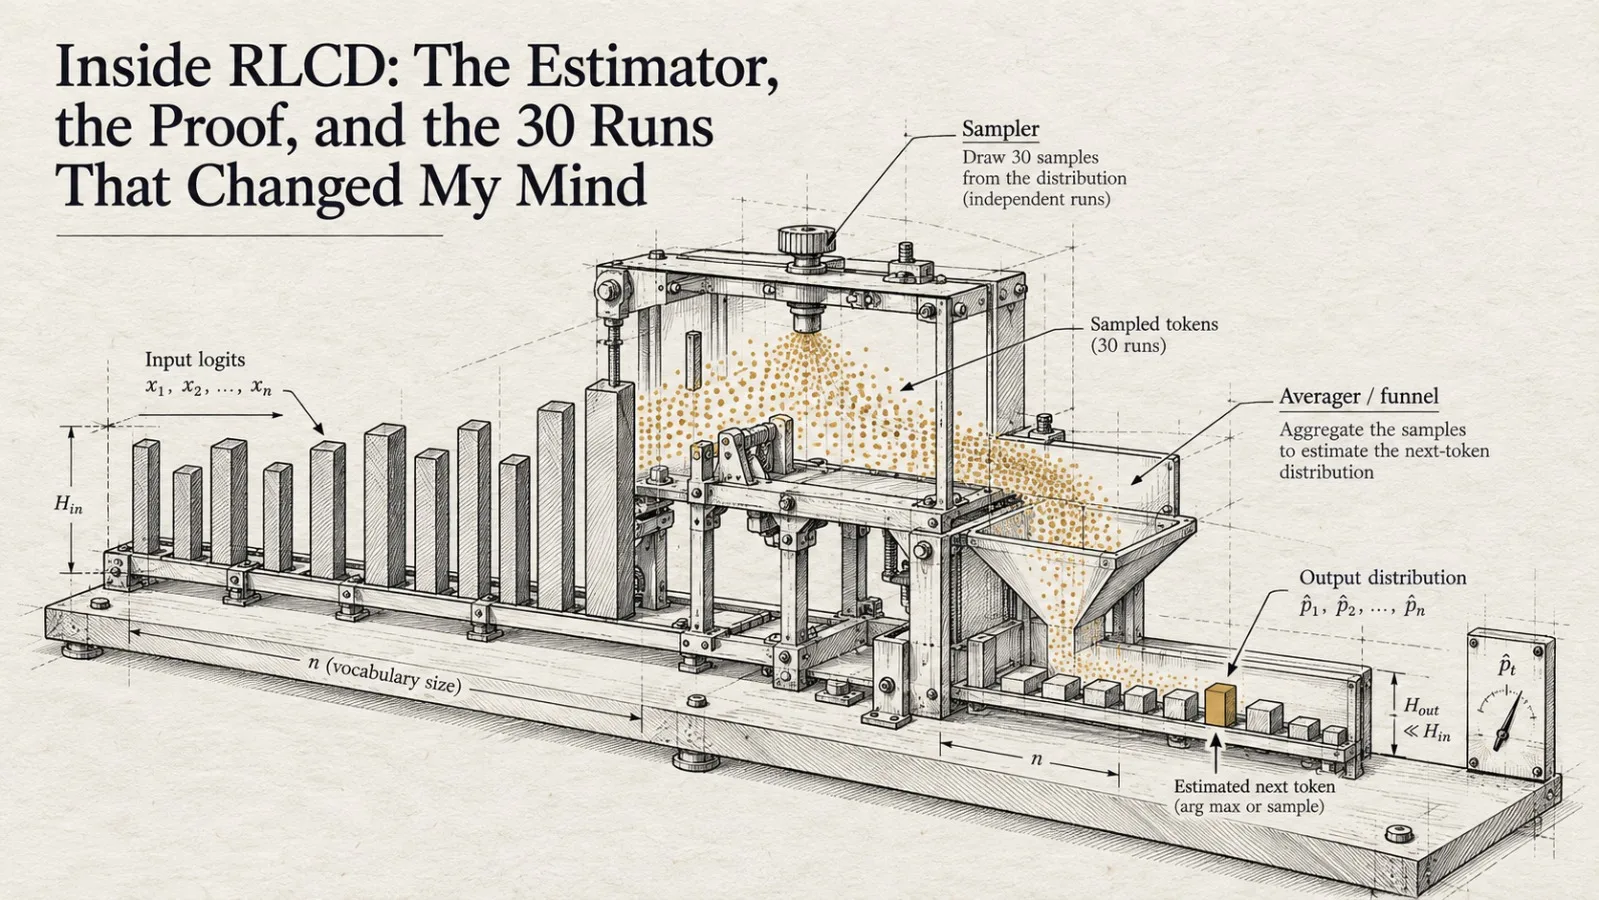
I went into this expecting the RL to be the interesting part. Laya's whole pitch is that a reinforcement-learning term turns noisy logits in...
Ollaya runs fast, calibrated decision models on your own hardware instead of a hosted API call, positioning itself against TypeSafe's closed...