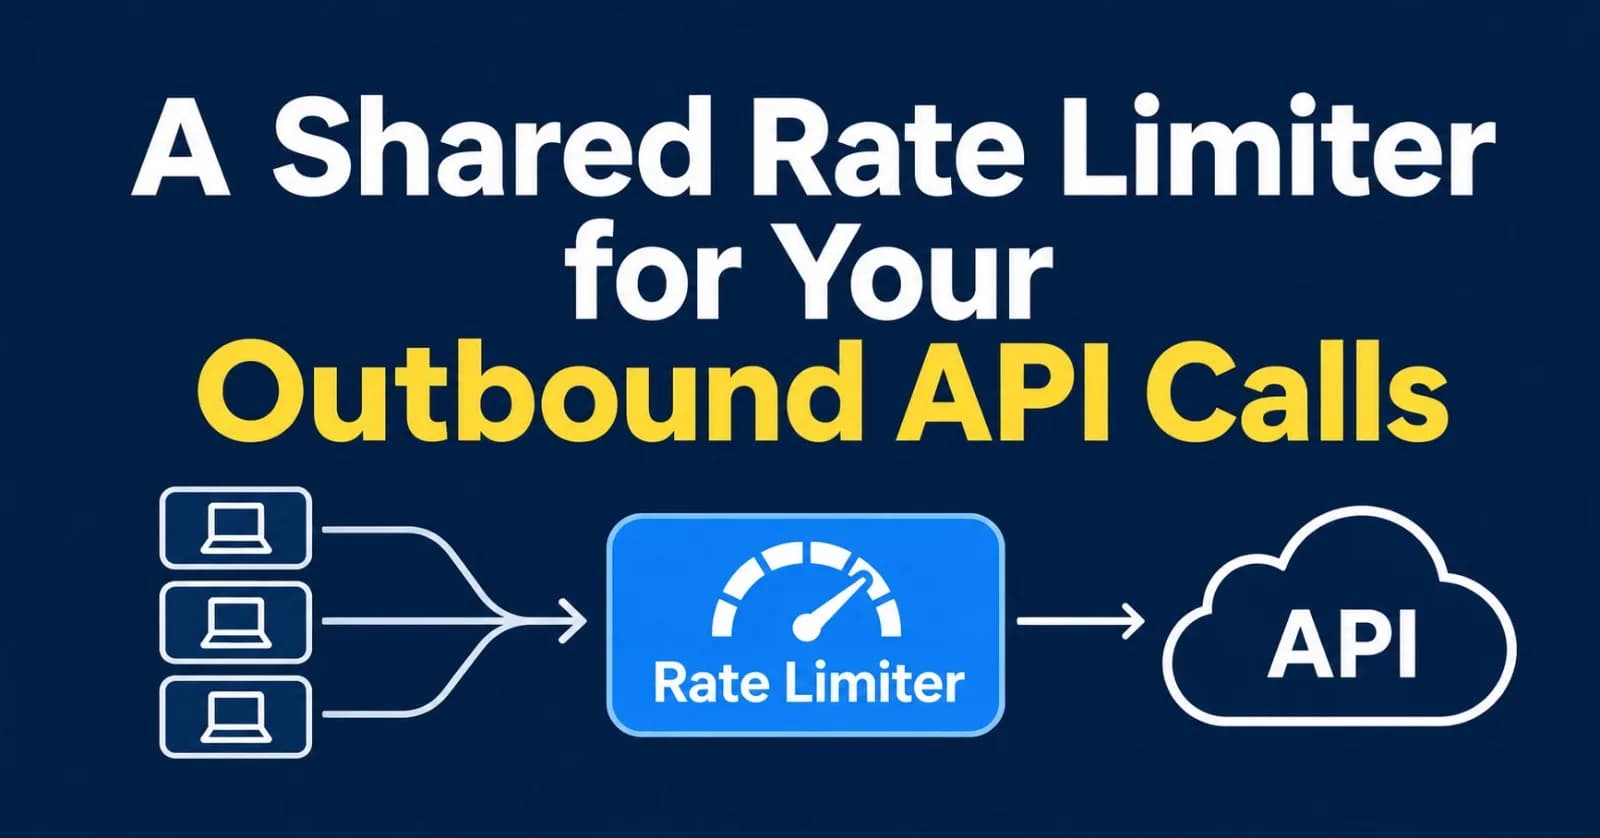
Most writing about rate limiting is about the receiving end: how to protect your API from clients. This post is about the other side. You are the client, a vendor says "10 requests per second," and going over means 429s, temporary bans, or a surprise bill.
With one script the fix is a one-liner:
time.sleep(0.1) # 10 requests per second, doneThen you add a second worker, a cron job that overlaps with the first, or a second server, and the one-liner quietly stops working. This post builds a limiter that every worker shares, using one row in the database you already run.
Why per-process limiters fall apart
Each worker obeys the limit on its own. Together they don't:
flowchart LR
    W1[Worker 1 at 10 req per sec] --> V[Vendor API with a limit of 10 req per sec]
    W2[Worker 2 at 10 req per sec] --> V
    W3[Worker 3 at 10 req per sec] --> V
    V --> R[30 req per sec arrive, so 429s and retries]
It gets worse from there. The usual reaction to a 429 is "retry after a bit," and every worker does that independently, so the retries land on top of fresh traffic. A small overload turns into a retry storm.
What you need is one place that all workers consult before every call. The limiter doesn't have to be fast or fancy. The vendor's own limit caps how often it can be called, so even a modest database handles it.
What are we limiting?
Vendors enforce three different kinds of limits, and it helps to know which one you have:
Request rate. "100 requests per minute," or "10 per second."
Cost-based rate. "40,000 tokens per minute," or a GraphQL query-cost budget. Different calls consume different amounts.
Concurrency. "At most 5 requests in flight." This is a semaphore, not a rate, and it needs a different tool.
The design below handles the first two with one mechanism. Concurrency limits are a separate problem, so I'll leave them out.
The idea: hand out time slots
The classic algorithms are fixed windows, sliding windows, and token buckets. Fixed windows allow double bursts at the window boundary. Sliding-window logs need to store every request. Token buckets work, but need two values per limit and some arithmetic to refill them.
There is a simpler formulation with a single value per limit: the next moment the API is free for us. This is the idea behind GCRA (the generic cell rate algorithm), which several production rate limiters use.
Think of a deli counter. Each caller takes the next free slot, and the next free slot then moves forward by one interval:
The limiter stores one timestamp,
next_slot.To make a call, a worker reserves a slot: its slot is
max(next_slot, now), andnext_slotadvances bycost × interval.The worker sleeps until its slot arrives, then makes the call.
sequenceDiagram
    participant W as Worker
    participant L as Limiter row in the DB
    participant V as Vendor API
    W->>L: reserve 1 slot
    L-->>W: your slot starts in 0.35 s
    Note over W: sleep 0.35 s
    W->>V: GET /resource
    V-->>W: 200 OK
Why this beats a counter:
One value, one atomic update. No window resets, no boundary spikes.
Callers learn exactly how long to wait, instead of looping on "try again."
It is naturally fair. Callers are served in the order they reach the lock.
Variable cost is free. A call that costs 5 units simply advances
next_slotby 5 intervals.
Postgres implementation
Schema
CREATE TABLE rate_limits (
    key           TEXT PRIMARY KEY,
    interval_secs DOUBLE PRECISION NOT NULL,            -- seconds between requests: 10/s -> 0.1
    burst_secs    DOUBLE PRECISION NOT NULL DEFAULT 0,  -- idle credit, see below
    next_slot     TIMESTAMPTZ NOT NULL DEFAULT now()
);

INSERT INTO rate_limits (key, interval_secs) VALUES ('vendor_x', 0.1);
Keeping the limit in the table means you can change it centrally, without redeploying every worker. Some conversions:
"600 requests per minute" →
interval_secs = 0.1"5,000 tokens per minute" →
interval_secs = 60.0 / 5000 = 0.012, and each call passes its token count ascost
Reserve a slot
The whole limiter is one statement:
UPDATE rate_limits
SET next_slot = GREATEST(next_slot, clock_timestamp() - burst_secs * interval '1 second')
              + (%(cost)s * interval_secs) * interval '1 second'
WHERE key = %(key)s
  AND GREATEST(next_slot, clock_timestamp() - burst_secs * interval '1 second')
      <= clock_timestamp() + %(max_wait)s * interval '1 second'
RETURNING GREATEST(
              0,
              EXTRACT(EPOCH FROM (next_slot - clock_timestamp()))::float8
              - %(cost)s * interval_secs
          ) AS wait_seconds;
Taking it apart:
GREATEST(next_slot, now)is the slot we claim. If the limiter has been idle, the slot is "now" and nobody waits. If it is busy, the slot is further in the future.The
WHEREclause is the safety valve. If the claimed slot is more thanmax_waitseconds away, the update matches no row and nothing is reserved. The caller can fail fast instead of joining an hour-long queue.RETURNINGcomputes how long to sleep. InRETURNING,next_slotis the new value, so subtractingcost × intervalgives the start of the slot we just claimed.Concurrency is handled by the row lock. Two workers updating the same row queue up behind each other, and the second one re-evaluates against the first one's result. This is the same guarantee that makes
UPDATE counters SET n = n + 1safe.clock_timestamp(), notnow().now()is frozen at the start of the transaction, which can be before the moment a blocked caller finally gets the lock.clock_timestamp()reads the real clock.
Run this in the default READ COMMITTED mode. Under REPEATABLE READ or SERIALIZABLE, concurrent updates to the same row raise serialization errors instead of queueing.
Wrapping it in Python
import time
import psycopg
from psycopg.rows import dict_row

DSN = "postgresql://app:secret@localhost:5432/app"

# autocommit: the row lock is released the instant the statement finishes
conn = psycopg.connect(DSN, autocommit=True, row_factory=dict_row)

ACQUIRE = """
UPDATE rate_limits
SET next_slot = GREATEST(next_slot, clock_timestamp() - burst_secs * interval '1 second')
              + (%(cost)s * interval_secs) * interval '1 second'
WHERE key = %(key)s
  AND GREATEST(next_slot, clock_timestamp() - burst_secs * interval '1 second')
      <= clock_timestamp() + %(max_wait)s * interval '1 second'
RETURNING GREATEST(
              0,
              EXTRACT(EPOCH FROM (next_slot - clock_timestamp()))::float8
              - %(cost)s * interval_secs
          ) AS wait_seconds
"""

class RateLimited(Exception):
    pass

def acquire(key, cost=1.0, max_wait=30.0):
    row = conn.execute(
        ACQUIRE, {"key": key, "cost": float(cost), "max_wait": float(max_wait)}
    ).fetchone()
    if row is None:   # also what you get for an unknown key, so seed your limits at startup
        raise RateLimited(f"{key}: next free slot is more than {max_wait}s away")
    if row["wait_seconds"] > 0:
        time.sleep(row["wait_seconds"])
Using it is one line before every outbound call:
acquire("vendor_x")
resp = session.get("https://api.vendor.example/v1/items", timeout=10)
If your workers use threads, give each thread its own connection (or use a connection pool) rather than sharing one.
Burst credit, and why it's off by default
burst_secs lets a limiter that has been idle send a few requests back-to-back. After an idle period, roughly burst_secs / interval_secs + 1 requests go out immediately, and then pacing resumes.
Leave it at 0 unless the vendor documents bucket-style bursts. A burst plus the steady rate can exceed a strict per-second window: with burst_secs = 0.5 at 10 requests per second, you can send 6 immediately and 9 more within the same second, which is 15 in a window where the vendor allows 10.
The same limiter on SQLite
If your workers are processes on one machine, you don't need a server at all. SQLite allows one writer at a time, and a single UPDATE ... RETURNING is atomic, so the same design works. You need SQLite 3.35 or newer for RETURNING.
# limiter.py
import sqlite3
import time

# autocommit, and wait for the write lock instead of failing
db = sqlite3.connect("limits.db", isolation_level=None, timeout=10)
db.row_factory = sqlite3.Row
db.execute("PRAGMA journal_mode = WAL")

db.execute("""
CREATE TABLE IF NOT EXISTS rate_limits (
    key           TEXT PRIMARY KEY,
    interval_secs REAL NOT NULL,             -- seconds between requests (10/s -> 0.1)
    burst_secs    REAL NOT NULL DEFAULT 0,   -- idle credit; leave at 0 unless the vendor allows bursts
    next_slot     REAL NOT NULL DEFAULT 0    -- unix time of the next free slot
)""")
db.execute("INSERT OR IGNORE INTO rate_limits (key, interval_secs) VALUES ('vendor_x', 0.1)")

# SQLite evaluates 'now' once per statement, so every use below sees the same instant
NOW = "((julianday('now') - 2440587.5) * 86400.0)"

ACQUIRE = f"""
UPDATE rate_limits
SET next_slot = max(next_slot, {NOW} - burst_secs) + :cost * interval_secs
WHERE key = :key
  AND max(next_slot, {NOW} - burst_secs) <= {NOW} + :max_wait
RETURNING max(0.0, next_slot - :cost * interval_secs - {NOW}) AS wait_seconds
"""

class RateLimited(Exception):
    pass

def acquire(key, cost=1.0, max_wait=30.0):
    """Reserve a slot, sleep until it arrives, then return. Raises if the wait would be too long."""
    # fetchall(), not fetchone(): let the statement finish so the write lock is released
    rows = db.execute(ACQUIRE, {"key": key, "cost": cost, "max_wait": max_wait}).fetchall()
    if not rows:  # also what you get for an unknown key, so seed your limits at startup
        raise RateLimited(f"{key}: next free slot is more than {max_wait}s away")
    wait = rows[0]["wait_seconds"]
    if wait > 0:
        time.sleep(wait)
    return wait

def penalize(key, seconds):
    """Push the next free slot out for every worker, e.g. after a 429 with Retry-After."""
    db.execute(f"UPDATE rate_limits SET next_slot = max(next_slot, {NOW} + ?) WHERE key = ?",
               (seconds, key))
Two SQLite specifics:
Keep
limits.dbon a local disk. WAL mode doesn't work reliably over network filesystems such as NFS.Never share one SQLite connection across
fork. Each worker process should open its own, which is why the test harness below usesspawn.
Make 429s a shared event
Even with a shared limiter, you'll still see the occasional 429. The vendor's limit may differ from the documentation, other clients may share your API key, or the vendor's window may not line up with yours.
The important move is to make the backoff shared too. When one worker gets a 429, every worker should slow down, not just the unlucky one. The limiter already has the right lever: push next_slot into the future.
-- Postgres
UPDATE rate_limits
SET next_slot = GREATEST(next_slot, clock_timestamp() + %(retry_after)s * interval '1 second')
WHERE key = %(key)s;
(The SQLite penalize() function above does the same thing.) In the call path:
def fetch(session, url):
    acquire("vendor_x")
    resp = session.get(url, timeout=10)
    if resp.status_code == 429:
        # Retry-After can also be an HTTP date; fall back to a default if it isn't a number
        try:
            delay = float(resp.headers.get("Retry-After", ""))
        except ValueError:
            delay = 5.0
        penalize("vendor_x", delay)
        raise RuntimeError("rate limited, will retry")   # let your retry layer handle it
    resp.raise_for_status()
    return resp
The retry itself then goes through acquire() again, so it waits its turn behind everyone else instead of piling on.
If the vendor sends headers like X-RateLimit-Remaining and X-RateLimit-Reset, you can use them the same way: when Remaining reaches zero, penalize until the reset time. Header names vary between vendors, so check the docs for the one you call.
Check that it works
Don't take the limiter's word for it. This script starts six worker processes, makes 60 calls through the limiter, and reports the busiest one-second window:
# check_limiter.py
import multiprocessing as mp
import time

def worker(n, out):
    from limiter import acquire          # imported in the child: one connection per process
    stamps = []
    for _ in range(n):
        acquire("vendor_x")
        stamps.append(time.time())       # the moment we would call the API
    out.put(stamps)

if __name__ == "__main__":
    ctx = mp.get_context("spawn")        # fresh interpreter per worker
    out = ctx.Queue()
    procs = [ctx.Process(target=worker, args=(10, out)) for _ in range(6)]
    for p in procs:
        p.start()
    stamps = sorted(t for _ in procs for t in out.get())
    for p in procs:
        p.join()

    worst = max(sum(1 for u in stamps if t <= u < t + 1.0) for t in stamps)
    print(f"{len(stamps)} calls in {stamps[-1] - stamps[0]:.1f}s, worst 1s window: {worst}")
With the 10-per-second limit from above, the 60 calls should take about 6 seconds. The worst one-second window should land at or just above 10, not at 30 or 60. It can be one or two above because sleep() is not perfectly precise, so a slot that wakes a few milliseconds late can sit next to one that wakes on time.
That leads to the most practical rule in this post: configure the limiter below the vendor's real limit. Running at 80 to 90 percent leaves headroom for sleep jitter, network timing, and vendors whose windows don't align with yours.
Don't sleep where you shouldn't
acquire() blocks. That is fine in a background worker and wrong in a web request handler, where a 20-second sleep ties up a thread and the user is staring at a spinner. Some patterns:
Request path: use a small
max_wait(say 0.5 seconds) and treatRateLimitedas "try again shortly" or "serve a cached result."Background jobs: instead of sleeping, return the wait to your scheduler and reschedule the job. If your queue stores a
run_attimestamp, set it tonow + wait_secondsand let the worker pick up other jobs in the meantime.asyncio: run the database call in a thread or use an async driver, then
await asyncio.sleep(wait). Never call a blockingacquire()directly inside an event loop.
Pitfalls
Calling
acquire()inside your business transaction. The row lock is held until that transaction commits, so every other worker waits behind all the work you do in it. Use a separate connection in autocommit mode.One key for everything. Vendors scope limits differently: per API key, per endpoint, per IP, per account. Make your keys match, for example
vendor_x:key_42:search. Two keys that the vendor counts together but you count separately will overshoot.Several pacing limits at once (say 10 per second and 300 per minute). Use one key per limit and acquire each. If a later one rejects the call, the slot reserved on the earlier one is wasted, which is safe but slightly wasteful.
Hard daily or monthly quotas are a different shape. They are counters, not pacing. Configuring a daily quota as an interval (86,400 seconds divided by the quota) would force calls to trickle out evenly all day. Track quotas with a plain counter row instead (
UPDATE ... SET used = used + 1 WHERE used < quota), and check it before you reserve a slot so a rejected call doesn't burn one.A hot row at huge rates. Every call updates one row, so callers are serialized on it. That comfortably covers typical vendor limits, but if a vendor allows very high rates, acquire in batches (
cost=100for 100 calls) or shard the key.What happens when the limiter is down? Decide on purpose. For vendors that ban on abuse, fail closed and wait. For soft limits, fail open at a conservative local rate, such as the vendor limit divided by the number of workers.
Forgetting that the limiter doesn't know about other clients. If someone else uses the same API key, your shared limiter can be perfect and you will still get 429s. That is what the shared penalty is for.
When Redis (or a library) is the better fit
Nothing here is anti-Redis. If you already run Redis, the same slot arithmetic fits in a short Lua script, which Redis executes atomically, and some modules and libraries package GCRA for you. Redis also makes sense when limits are numerous and short-lived (per-user, per-IP) or when you need very high call rates.
If you'd rather not own the code, there are good libraries:
In-process only: Go's
golang.org/x/time/rate, Python'saiolimiter. These are fine for a single process and don't help across workers.Shared across processes: Bottleneck with its Redis clustering (Node),
redis_rate(Go), and thelimitslibrary with a Redis backend (Python).
For a handful of vendors with modest limits, though, one table is hard to beat. There is no extra service to run, the state survives deploys, and you can inspect it with a SELECT.
Takeaways
Per-process throttling breaks the moment you run a second worker. Share the limiter.
Store one timestamp per limit: the next free slot. Reserve with a single atomic
UPDATE ... RETURNINGand sleep exactly as long as it says.Add
max_waitso callers fail fast instead of joining a huge queue.Make 429s a shared event by pushing
next_slotout for everyone.Run the limiter below the vendor's limit, and verify it with a multi-process test.
Never call
acquire()inside a long transaction, and don't block request handlers.
Comments(0)
Join the discussion by logging into your account.
No comments yet. Be the first to comment!