
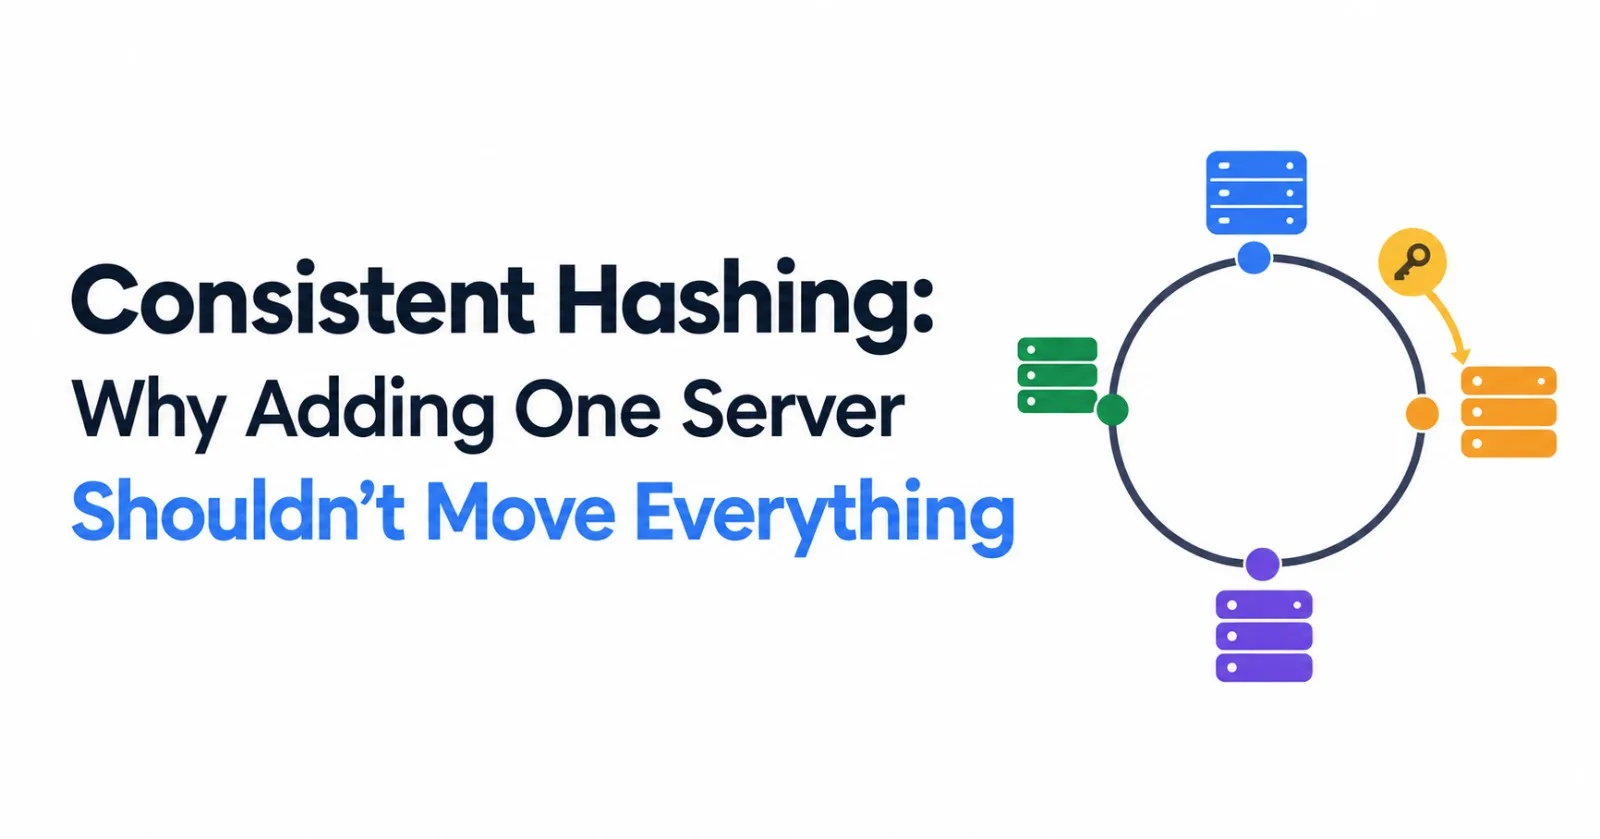
Add a fifth server to a four-server cache cluster. With the obvious approach, hash(key) % number_of_servers, something like 80% of your keys suddenly belong to a different server than they did a minute ago. Every one of those keys is now a cache miss. Every one of those cache misses hits your database at once.
Consistent hashing exists to prevent exactly that — it's why DynamoDB, Cassandra, and most distributed caches can scale without a self-inflicted thundering herd.
The Problem With hash(key) % N
Modulo-based sharding is intuitive: hash the key, take the remainder when divided by the number of servers, and that remainder tells you which server owns it. The problem is that N is baked directly into every single assignment. Change N by even one, and the remainder for almost every key changes along with it, because the modulo operation has no memory of what the previous assignment was.
Putting Servers and Keys on the Same Ring
Consistent hashing changes the model entirely. Picture a clock face instead of a number line: both the servers and the keys get hashed onto the same circle, so everything ends up sitting at some position on the dial. (A real implementation uses billions of positions instead of twelve, but the clock-face idea is all you need.)
To find which server owns a key: hash the key to find its spot on the dial, then move clockwise until you land on a server. Whichever one you hit first, owns that key. That's the entire lookup.
In practice, nothing actually "walks" anywhere — positions live in a sorted list, and finding the right server is one binary search: O(log V). Even a ring with millions of points needs just a handful of comparisons.
When a new server joins, it only intercepts keys sitting in the small stretch of the dial right before it — everyone else's assignment stays exactly the same. When a server leaves, its keys simply spill over to whichever server is next going clockwise, and nothing else changes.
A Tiny, Walkable Example
Forget real hash functions for a moment and use a ring of just 100 positions (0 to 99). Three servers sit on it: A at 10, B at 40, C at 75. Three keys hash to positions 25, 45, and 95.
Walking clockwise from each key to the first server: key 25 lands on B, key 45 lands on C, and key 95 wraps past 99 back to 0 and lands on A.
Now add a fourth server, D, at position 50:
Key
25still walks straight intoBat 40 —Dis further away and never comes into play. No change.Key
45now hitsDat 50 before it ever reachesCat 75. It moves, fromCtoD.Key
95still wraps around toAat 10, completely unaffected by anything near position 50. No change.
Only the key sitting in the stretch immediately behind D — between B and D — ever noticed a new server showed up. Everything else on the ring didn't have to care.
Proving It: Real Rehashing Numbers
Take 100,000 keys, assign them across 4 servers, then add a 5th, and count how many keys land on a different server than before.
import hashlib, bisect

def h(key):
    return int(hashlib.md5(key.encode()).hexdigest(), 16)

def naive_assign(keys, num_servers):
    return {key: h(key) % num_servers for key in keys}

class ConsistentHashRing:
    def __init__(self, servers, vnodes=150):
        self.ring = {}
        for server in servers:
            for i in range(vnodes):
                pos = h(f"{server}#{i}")
                self.ring[pos] = server
        self.sorted_positions = sorted(self.ring.keys())

    def get_server(self, key):
        pos = h(key)
        idx = bisect.bisect(self.sorted_positions, pos)
        if idx == len(self.sorted_positions):
            idx = 0
        return self.ring[self.sorted_positions[idx]]
Naive hash%N: 80,087/100,000 keys moved (80.1%)
Consistent hashing: 18,519/100,000 keys moved (18.5%)Naive modulo hashing reshuffles 80% of the entire dataset for a 25% capacity increase. Consistent hashing moves almost exactly what theory predicts it should — 1 divided by the new server count (1/5 = 20%) — and nothing more. Every key that didn't need to move, didn't.
The Catch: Uneven Load, and the Fix
Placing each server at just one random point on the ring has a problem of its own: with only a handful of random points, the arcs between them can be wildly uneven in size, and so can the load.
vnodes=  1:  min=1,332   max=40,206   stdev=18,565
vnodes=150:  min=18,340  max=22,565   stdev=1,766
With one ring position per server, one server ended up owning 40,206 keys while another owned just 1,332 — a 30x imbalance, from the same 5 servers and the same 100,000 keys.
The fix is virtual nodes: instead of placing each physical server once, place it 100 to 200 times at different hashed positions on the ring. More points per server means the randomness has more chances to average out, so the arcs even out. When a server does leave, its load spreads across many other servers instead of dumping entirely onto its single ring neighbor.
Weighted Consistent Hashing
Virtual nodes assume every server is equally capable, but real clusters are rarely that tidy — one box might have three times the RAM or CPU of another. The fix is a small variation on the same idea: give bigger servers proportionally more virtual nodes instead of an equal share.
import hashlib, bisect

def h(key):
    return int(hashlib.md5(key.encode()).hexdigest(), 16)

class WeightedRing:
    def __init__(self, server_weights, base_vnodes=50):
        self.ring = {}
        for server, weight in server_weights.items():
            for i in range(base_vnodes * weight):
                pos = h(f"{server}#{i}")
                self.ring[pos] = server
        self.sorted_positions = sorted(self.ring.keys())

    def get_server(self, key):
        pos = h(key)
        idx = bisect.bisect(self.sorted_positions, pos)
        if idx == len(self.sorted_positions):
            idx = 0
        return self.ring[self.sorted_positions[idx]]

weights = {"A": 1, "B": 1, "C": 3}  # C is a 3x-larger box
ring = WeightedRing(weights)
Testing that against 100,000 keys, where A and B are equal-sized and C is sized for three times the load:
A (weight 1): expected 20.0%, got 19.7%  (19,689 keys)
B (weight 1): expected 20.0%, got 22.8%  (22,829 keys)
C (weight 3): expected 60.0%, got 57.5%  (57,482 keys)
Close enough to the target split to be genuinely useful in practice. The small deviation — B ended up a bit ahead of A despite an identical weight — is just the expected noise from a finite, randomly-hashed sample, and it shrinks further as vnode counts increase. This is exactly how a cluster with mismatched hardware avoids either starving its small boxes or overloading its big ones.
Where This Shows Up in Production
Amazon's Dynamo (and DynamoDB after it) popularized consistent hashing with virtual nodes as the core partitioning strategy for a distributed key-value store designed to scale without downtime.
Apache Cassandra uses consistent hashing with virtual nodes to spread data across the cluster and rebalance automatically as nodes join or leave.
Memcached client libraries (the well-known
libketamaimplementation) use it so that adding a cache server doesn't invalidate the entire cache at once.Load balancers and CDNs use it to route requests so a given client or resource consistently lands on the same backend, without every backend change reshuffling all the traffic.
A Related Approach: Rendezvous Hashing
Consistent hashing isn't the only way to solve this problem. Rendezvous hashing, also called highest random weight (HRW), skips the ring entirely: for a given key, compute a combined hash of (key, server) for every server, and assign the key to whichever server produces the highest score.
Adding or removing a server changes that comparison, not any stored structure — the same minimal-movement result through a different mechanism. It trades the ring's O(log V) lookup for an O(N) scan, checking every server one by one: fine for a small cluster, less appealing for a very large one.
The Takeaway
Consistent hashing doesn't eliminate data movement when your cluster changes; a fifth of the keys above still had to move, and that's expected and fine. What it eliminates is the unnecessary movement — the other 80% that a naive modulo would have shuffled around for no real reason.
Combined with virtual nodes (weighted, if your hardware isn't uniform) to keep the load even, it's the reason a distributed system can grow or shrink its capacity as a routine operation instead of a disruptive one.
Comments (0)
Login to post a comment.