Mistral Large 4 : A Trillion-Parameter Preview With Open Weights on the Way
Mistral Large 4 is a 1.05T-parameter MoE model with a 1M-token advertised context, strong coding and cybersecurity results, and open weights...
Oct 6, 2026
10 min
Mistral Large 4 is a 1.05T-parameter MoE model with a 1M-token advertised context, strong coding and cybersecurity results, and open weights...
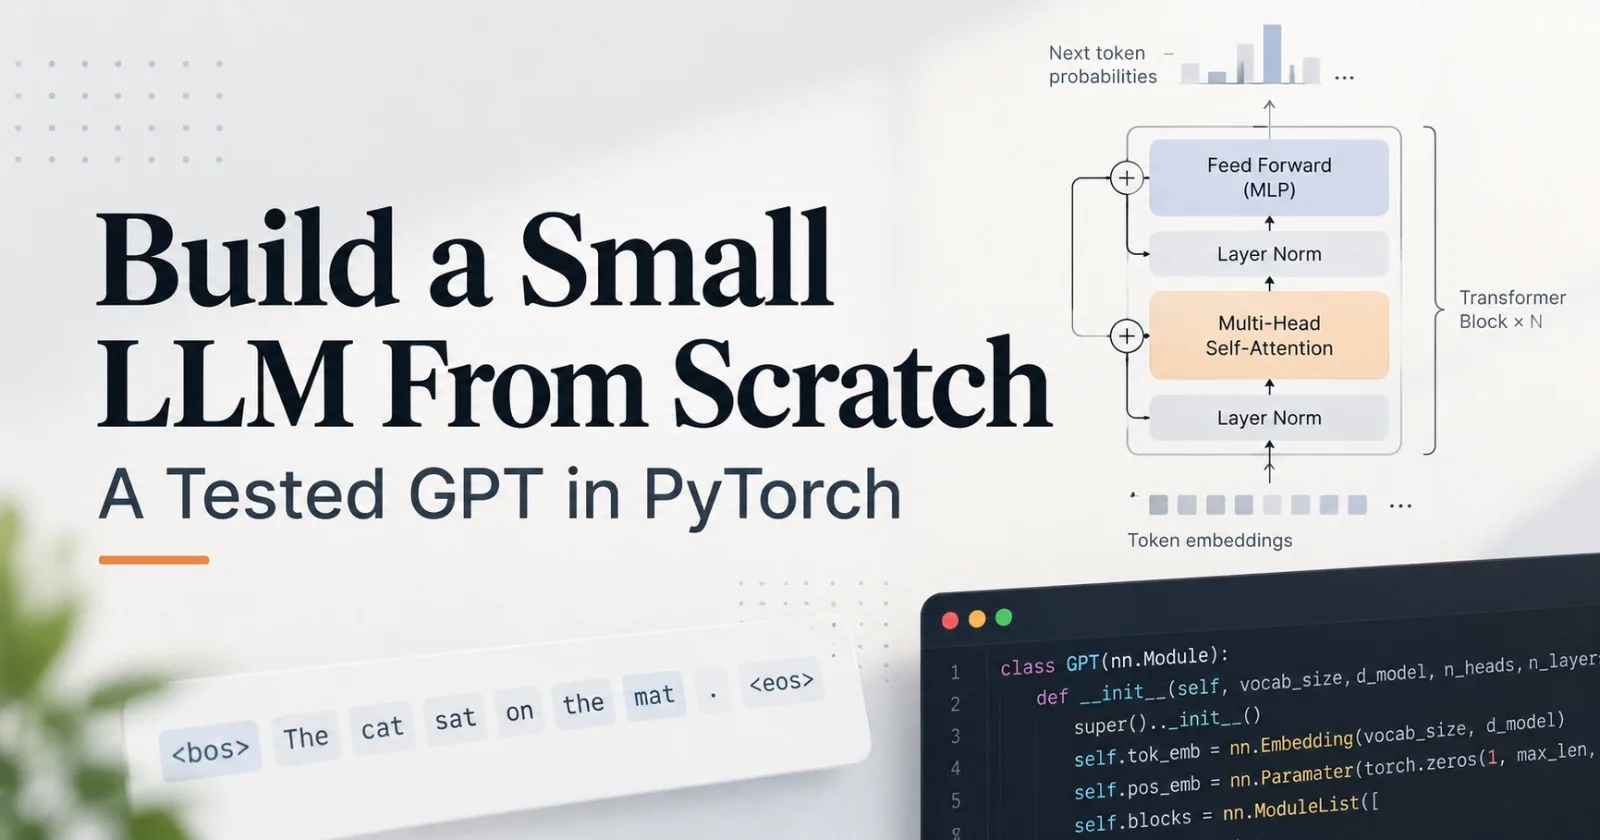
A practical, fully tested GPT implementation in PyTorch with causal attention, training, sampling, baselines, checkpoints, and 25 tests. Tra...
Tencent’s Hy4 Preview doubles down on sparse architecture and long-context efficiency. Here’s what changed from Hy3, what the benchmarks rea...