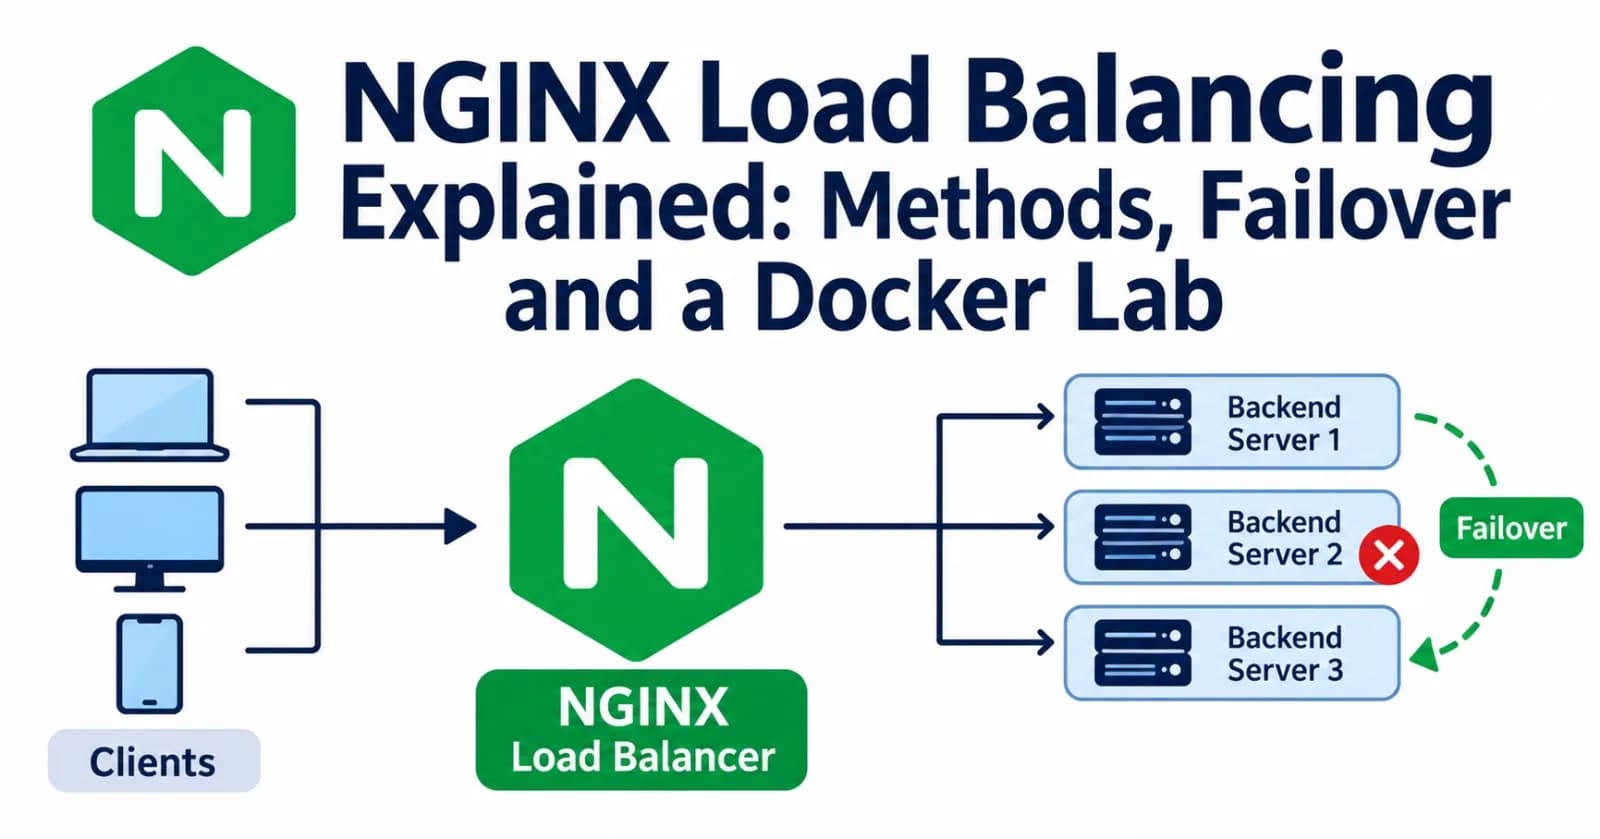
A load balancer spreads requests across several copies of your app, and nginx can do that job in about ten lines of config. Surviving a failure takes a few more, because the defaults leave gaps. Left alone, nginx can wait up to a minute to connect to a dead server, and it only learns a server is down when a real user's request fails.
That leaves three questions:
Which method should pick the server?
How does nginx decide a server is dead?
What happens to a request whose server dies halfway through?
In this guide we build a small lab with Docker Compose, three backends behind nginx, and use it to try each idea. The directives are checked against the official nginx documentation, and I note the version where a feature needs a recent release. At the time of writing, nginx stable is 1.30 and mainline is 1.31.
The 30-second version
You list your servers in an upstream block and point proxy_pass at it. nginx picks a server for each request. If talking to that server fails, nginx passes the request to the next one.
flowchart LR
    client["Clients"] --> nginx["nginx, upstream app"]
    nginx --> app1["app1"]
    nginx --> app2["app2"]
    nginx --> app3["app3"]
Out of the box, the picking is weighted round robin, which means servers take turns, and a server with a higher weight takes more turns. Everything else in this post is a way to change who gets the next request, or what happens when a server misbehaves.
The lab
You need Docker with Compose. The backend is a 30-line Python server that answers with its own name, can be made slow with an environment variable, and echoes request headers at /headers:
# app.py
import os
import time
from http.server import BaseHTTPRequestHandler, ThreadingHTTPServer

NAME = os.environ.get("NAME", "app")
DELAY = float(os.environ.get("DELAY", "0"))     # seconds to hold every request
PORT = int(os.environ.get("PORT", "8000"))


class Handler(BaseHTTPRequestHandler):
    protocol_version = "HTTP/1.1"                # lets nginx reuse connections

    def do_GET(self):
        time.sleep(DELAY)
        if self.path == "/headers":              # show what nginx forwarded to us
            body = "".join(f"{k}: {v}\n" for k, v in self.headers.items())
        else:
            body = f"{NAME}\n"
        data = body.encode()
        self.send_response(200)
        self.send_header("Content-Type", "text/plain")
        self.send_header("Content-Length", str(len(data)))
        self.end_headers()
        self.wfile.write(data)

    def log_message(self, *args):                # keep container logs quiet
        pass


ThreadingHTTPServer(("0.0.0.0", PORT), Handler).serve_forever()
Compose runs three copies of it plus nginx. The APP3_DELAY variable lets us make app3 slow later without editing the file:
# docker-compose.yml
x-app: &app
  image: python:3.12-alpine
  command: python /app/app.py
  volumes:
    - ./app.py:/app/app.py:ro

services:
  app1:
    <<: *app
    environment:
      NAME: app1
  app2:
    <<: *app
    environment:
      NAME: app2
  app3:
    <<: *app
    environment:
      NAME: app3
      DELAY: "${APP3_DELAY:-0}"      # set APP3_DELAY=1 to make app3 slow

  nginx:
    image: nginx:stable
    ports:
      - "8080:80"
    volumes:
      - ./default.conf:/etc/nginx/conf.d/default.conf:ro
    depends_on:
      - app1
      - app2
      - app3
The nginx config starts as plain round robin. The log_format is the important part: $upstream_addr shows which backend actually served each request, and $upstream_status shows what it answered. Those two variables make every experiment in this post visible. The file goes in conf.d, which the official image includes inside the http block, so upstream and log_format are in the right place.
# default.conf
log_format lb '$remote_addr -> $upstream_addr status=$upstream_status '
              'rt=$upstream_response_time "$request"';

upstream app {
    server app1:8000;
    server app2:8000;
    server app3:8000;
}

server {
    listen 80;
    access_log /var/log/nginx/access.log lb;

    location / {
        proxy_pass http://app;
        proxy_set_header Host              $host;
        proxy_set_header X-Real-IP         $remote_addr;
        proxy_set_header X-Forwarded-For   $proxy_add_x_forwarded_for;
        proxy_set_header X-Forwarded-Proto $scheme;
    }
}
Start it and count where 12 requests land:
docker compose up -d
for i in $(seq 1 12); do curl -s localhost:8080; done | sort | uniq -c
You should see the three names with four requests each:
4 app1
      4 app2
      4 app3
After any config change, check it and reload:
docker compose exec nginx nginx -t
docker compose exec nginx nginx -s reload
Run nginx -t every time. A typo that stops nginx from loading is much easier to catch there than in production. When you are done with the lab, docker compose down removes it.
Weights
A weight sets a server's share of the traffic. The default is 1.
upstream app {
    server app1:8000 weight=3;
    server app2:8000;
    server app3:8000;
}
Now app1 takes 3 of every 5 requests. Reload, run the counting loop again with seq 1 15, and you should see 9 requests for app1 and 3 each for the others. Use weights when servers are not equal, such as a bigger machine next to smaller ones, or when you want to send a canary a small share of traffic.
Choosing a method
Round robin is a fine default, and the right answer more often than people expect. Reach for something else only when you have a reason.
flowchart TD
    start["Must one client keep hitting the same server?"]
    start -->|"No"| uneven["Are request durations very uneven, or connections long-lived?"]
    uneven -->|"No"| rr["Round robin, the default"]
    uneven -->|"Yes"| lc["least_conn"]
    start -->|"Yes"| key["Do you have a good key, like a session cookie or a URL?"]
    key -->|"Yes"| hash["hash key consistent"]
    key -->|"No"| ip["sticky cookie, or ip_hash"]
least_conn
Sends each request to the server with the fewest active connections, taking weights into account. It helps when some requests are much slower than others, such as uploads, reports or WebSockets, because a plain round robin keeps feeding a server that is already busy.
upstream app {
    least_conn;
    server app1:8000;
    server app2:8000;
    server app3:8000;
}
You can see the difference in the lab:
Make
app3slow, then send 60 requests, 10 at a time, with the round robin config you have now.Add
least_conn;to theupstreamblock and reload.Send the same 60 requests again.
APP3_DELAY=1 docker compose up -d app3

# run this line in steps 1 and 3
seq 60 | xargs -P 10 -I{} curl -s localhost:8080 | sort | uniq -c
With round robin, each server gets an equal share even though app3 is holding connections for a second each. With least_conn, app3 should end up with noticeably fewer requests, because it is busy and the others are not.
ip_hash
Maps a client IP address to a server, so the same client keeps landing on the same one. It uses the first three octets of an IPv4 address, or the whole IPv6 address, so every client in the same /24 network goes to the same server. If you need to take a server out of an ip_hash group temporarily, mark it down instead of deleting it, so the existing mapping is preserved.
hash
Does the same with any key you choose. The consistent parameter matters when you add or remove servers: without it, most keys can move to a different server, and with it only a few do. That is what you want in front of caches.
upstream app {
    hash $request_uri consistent;
    server app1:8000;
    server app2:8000;
    server app3:8000;
}
If the key is empty, for example a cookie the client doesn't have yet, nginx falls back to round robin for that request.
random two
Picks two servers at random, then sends the request to the one with fewer connections. It gets most of the benefit of least_conn, and it avoids several nginx instances all picking the same "least busy" server at once.
upstream app {
    random two least_conn;
    server app1:8000;
    server app2:8000;
    server app3:8000;
}
least_time
Prefers the server with the lowest average response time. It is available in open source nginx from mainline 1.31.0. On the 1.30 stable branch it needs NGINX Plus.
Sticky sessions
Sometimes a client must come back to the same server, for example because the app keeps sessions in memory. You have three options, and the best one is the last.
Option 1: ip_hash
ip_hash is the simplest, with two weaknesses. Many users can share one IP address (an office, a mobile carrier), which skews the load. And if another proxy or CDN sits in front of nginx, the address nginx sees is the proxy's, so everyone looks like one client.
Option 2: a sticky cookie
A cookie solves both. Since nginx 1.29.6, and so in the 1.30 stable branch, the sticky directive is available in open source nginx:
upstream app {
    server app1:8000;
    server app2:8000;
    server app3:8000;

    sticky cookie srv_id expires=1h path=/ httponly samesite=lax;
}
nginx sets the cookie on a client's first request and routes on it afterwards. If the chosen server can't handle a request, nginx picks another one as if the client had no cookie yet. The same release added a drain parameter for deployments: a server marked drain only receives requests from clients already bound to it, so you can take it out of rotation gradually.
Option 3: no stickiness at all
The best option is to avoid needing stickiness at all. Keep sessions in Redis or a database, or use signed tokens, and any server can handle any request. Then every server is interchangeable, and failover is trivial.
When a server fails
nginx's built-in failure detection is passive. It watches real traffic instead of probing servers on its own. Two parameters on each server control it:
max_failsis how many failed attempts, withinfail_timeout, mark the server unavailable. The default is 1.fail_timeoutis both the window for counting failures and how long the server stays out of rotation. The default is 10 seconds.
stateDiagram-v2
    direction LR
    [*] --> Available
    Available --> Unavailable: max_fails failures within fail_timeout
    Unavailable --> Probing: fail_timeout elapsed
    Probing --> Available: a real request succeeds
    Probing --> Unavailable: the request fails
Note what the probe is: after fail_timeout, nginx tries the server again with a real client request. If it is still down, one user pays for that discovery, once per fail_timeout. This is the main limit of passive checks, and the reason active health checks exist (more on that below).
Try it in the lab:
docker compose stop app2
for i in $(seq 1 12); do curl -s localhost:8080; done | sort | uniq -c
docker compose logs nginx | tail -20
Every request still succeeds, now split between app1 and app3. In the log, the request that discovered the failure shows two addresses in $upstream_addr, the dead one first. The first request may also be slow: nginx waited for the connection attempt to fail.
sequenceDiagram
    participant C as Client
    participant N as nginx
    participant A2 as app2, down
    participant A3 as app3
    C->>N: GET /
    N->>A2: connect
    A2--xN: connection error or timeout
    Note over N: counts a failure for app2
    N->>A3: same request, next server
    A3-->>N: 200
    N-->>C: 200
If every server in the group fails, nginx has nowhere left to go and returns 502 Bad Gateway, or 504 Gateway Timeout when the attempts timed out.
What counts as a failure
This is decided by proxy_next_upstream, which goes in the location (or server or http) block, not in upstream. The default is error timeout: connection errors and timeouts count, and the request moves on to the next server. Other conditions you can add:
http_502 http_503 http_504(andhttp_500,http_429) treat those responses as failures. A 502 from a crashed backend usually means "try another server", so adding these is common.invalid_headercounts an empty or invalid response.http_403andhttp_404can be listed to trigger a retry, but they are never counted towardmax_fails.
Three more settings keep retries safe and fast:
location / {
    proxy_pass http://app;

    proxy_connect_timeout 2s;
    proxy_next_upstream error timeout http_502 http_503 http_504;
    proxy_next_upstream_tries 3;
    proxy_next_upstream_timeout 10s;
}proxy_connect_timeoutdefaults to 60 seconds. For a dead server that is a very long time to make a user wait. Two or three seconds is usually plenty on a healthy network.proxy_next_upstream_triesandproxy_next_upstream_timeoutcap how many servers one request may try and the total time spent trying. Both default to 0, which means no cap.
Since nginx 1.9.13, requests with non-idempotent methods (POST, LOCK, PATCH) are not passed to the next server once they have been sent to a backend, because retrying could repeat a payment or a write. If your endpoints are safe to retry, you can add non_idempotent to proxy_next_upstream. Do that only when you are sure, ideally with idempotency keys.
Spare servers and one server
Mark a server backup and it only gets traffic when the primary servers are unavailable. Mark it down to take it out of rotation. The backup parameter cannot be combined with hash, ip_hash or random.
upstream app {
    server app1:8000 max_fails=3 fail_timeout=15s;
    server app2:8000 max_fails=3 fail_timeout=15s;
    server app3:8000 backup;
}
Try it with this config: stop app1 and app2, and app3 takes over. One gotcha: if a group has a single server, max_fails and fail_timeout are ignored and that server is never considered unavailable.
Share state between workers
nginx runs several worker processes. Without a zone, each worker keeps its own copy of the run-time state, so failure counts and connection limits are per worker, not global. Add a shared memory zone to the group:
upstream app {
    zone app 64k;
    least_conn;
    server app1:8000;
    server app2:8000;
    server app3:8000;
}
Connection reuse and protecting backends
Opening a new TCP connection for every proxied request is wasteful. Since nginx 1.29.7, connections to upstream servers are kept alive by default, and proxy_http_version defaults to 1.1, so you get this for free on the current stable branch. On older versions you had to add it yourself:
upstream app {
    server app1:8000;
    keepalive 32;
}

location / {
    proxy_pass http://app;
    proxy_http_version 1.1;
    proxy_set_header Connection "";
}
The number after keepalive is the maximum count of idle connections cached per worker. It does not limit the total number of connections nginx opens to a backend. To cap that, use max_conns on the server, and put the group in a shared zone so the limit is global instead of per worker.
server app1:8000 max_conns=100;Passing client information through
Behind a proxy, your app sees nginx as the client. The proxy_set_header lines in the lab config pass the real details along. The Python backend can show you what it received:
curl -s localhost:8080/headersYou should see X-Real-IP, X-Forwarded-For and X-Forwarded-Proto among the headers. Your app should read the client address from those, and only trust them when the request really came through your own proxy.
Changing the pool without downtime
Reloading with nginx -s reload is graceful: new workers start with the new config, and old workers finish their current requests before they exit. That covers adding, removing and re-weighting servers.
One thing catches people out: nginx resolves the hostnames in an upstream block when it loads the config. If a name cannot be resolved at that moment, nginx refuses to start, which is why the lab uses depends_on. If a backend's IP changes later, nginx keeps using the old one until the next reload.
Since nginx 1.27.3, open source nginx can re-resolve names while running. It needs a zone, a resolver, and the resolve parameter on the server:
upstream app {
    zone app 64k;
    resolver 127.0.0.11 valid=10s;

    server app1:8000 resolve;
}
Here 127.0.0.11 is Docker's built-in DNS. Use your own DNS server's address elsewhere. A hostname that resolves to several IP addresses defines several servers at once.
What still needs NGINX Plus
The open source version covers a lot now. These are the features that still need the commercial NGINX Plus:
Feature | What it does |
|---|---|
Active health checks ( | Probes servers on a schedule, without waiting for a real request to fail |
| Ramps a recovered server's traffic up gradually |
Runtime API for upstreams | Adds, removes and re-weights servers without a reload |
Request queue ( | Holds requests briefly when every server is busy |
Everything else in this post works in open source nginx, on the versions noted where a feature is recent.
If you need active health checks on open source nginx, the usual workaround is to let your orchestrator remove unhealthy backends from the pool, then reload nginx. In Kubernetes, readiness checks do that job for you.
A starting config for production
Putting the pieces together, this is a sensible starting point for a stateless app. It uses the default round robin, so add least_conn; if your request times vary a lot:
upstream app {
    zone app 64k;

    server app1:8000 max_fails=3 fail_timeout=15s;
    server app2:8000 max_fails=3 fail_timeout=15s;
    server app3:8000 max_fails=3 fail_timeout=15s;
}

server {
    listen 80;

    location / {
        proxy_pass http://app;
        # plus the four proxy_set_header lines from the lab config

        proxy_connect_timeout 2s;
        proxy_next_upstream error timeout http_502 http_503 http_504;
        proxy_next_upstream_tries 3;
        proxy_next_upstream_timeout 10s;
    }
}
Two reminders go with it. A single nginx is itself a single point of failure, so production setups run at least two behind a floating IP or a cloud load balancer. And keep nginx updated: the 1.30 stable branch has received several security fixes this year, so run the latest 1.30.x release rather than the first one you find in a package repository.
Wrap-up
Pick a method, and stay with round robin until something proves you wrong. Decide what counts as a failure, and keep timeouts short enough that users never wait on a dead server. Make the balancing visible with $upstream_addr in your logs, because a balancer you cannot observe is one you cannot trust.
Not covered here: TLS termination, WebSocket upgrades, and balancing raw TCP or UDP with the stream module. Each is a post of its own.
Further reading
proxy_next_upstreamin the proxy module reference
Comments(0)
Join the discussion by logging into your account.
No comments yet. Be the first to comment!