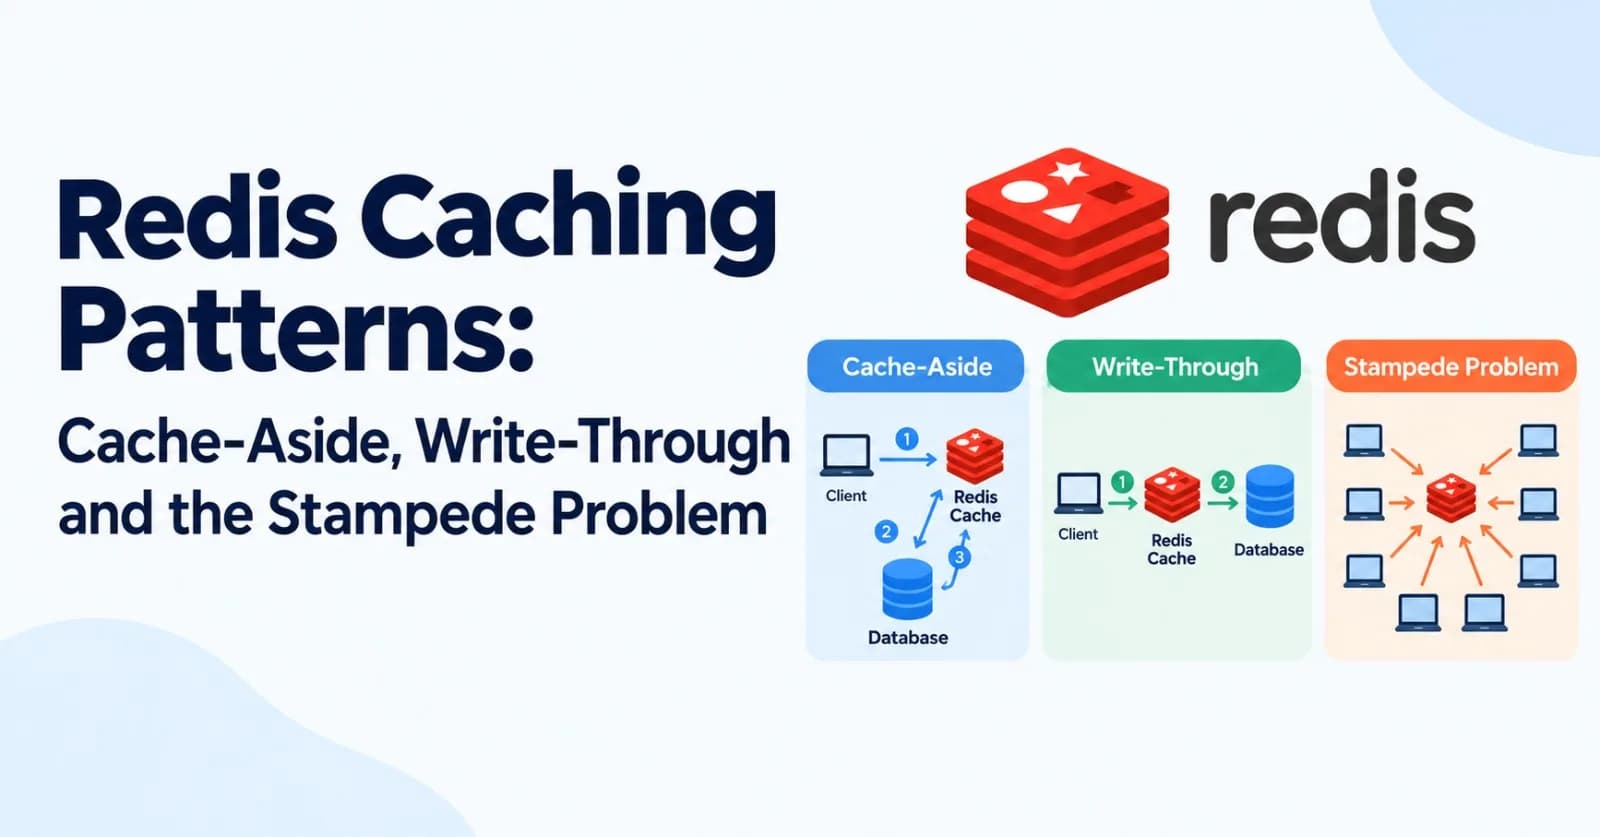
Caching looks like the easiest win in backend work. Put Redis in front of the slow query and the page loads in 5 ms instead of 300.
Then the problems show up, one at a time. Users edit something and still see the old version. A hot key expires at 9:00:00 and fifty requests hit your database in the same second. Redis restarts and the whole app crawls.
None of this is exotic. These are the standard failure modes of the standard patterns.
This post covers the patterns, where each one breaks, and tested fixes. The code is Python, but the ideas apply to any language.
Everything here runs against an in-memory stand-in for Redis, so you can try it without installing anything. A real RedisStore is included for when you're ready.
The patterns at a glance
There are four names you'll hear:
Pattern | Who loads the data | How data gets into the cache | Main risk |
|---|---|---|---|
Cache-aside (also called lazy loading) | Your app | On a miss, the app loads from the database and stores the result | Stale data, slow misses, stampedes |
Read-through | The cache layer | Same idea, but the cache calls your loader for you | The same, and you need a cache that supports loaders |
Write-through | Your app, or the cache layer | Every write updates the database and the cache | Slower writes, and a cache full of data nobody reads |
Write-behind | The cache layer, later | Writes land in the cache and are flushed to the database asynchronously | Data loss if the cache dies before it flushes |
Most teams use cache-aside for reads, plus either delete-on-write or write-through for updates, plus a TTL as a safety net. That combination is what we'll build.
Write-behind needs a warning. Redis keeps data in memory, so a crash between "written to the cache" and "flushed to the database" can lose that write. Persistence settings narrow the window but don't close it. Use it only when you can afford to lose recent writes.
The building blocks
Everything goes through five operations. Here's the real Redis adapter:
class StoreUnavailable(Exception):
    """The cache server can't be reached. The app should carry on without it."""


# From the Redis docs: only delete the lock if it still holds OUR token.
RELEASE_LOCK = """
if redis.call("get", KEYS[1]) == ARGV[1] then
    return redis.call("del", KEYS[1])
else
    return 0
end
"""


class RedisStore:
    """The five operations the cache needs, on top of redis-py."""

    def __init__(self, url="redis://localhost:6379/0"):
        import redis

        self._redis = redis
        self._client = redis.Redis.from_url(
            url, decode_responses=True, socket_timeout=0.1, socket_connect_timeout=0.1
        )
        self._release = self._client.register_script(RELEASE_LOCK)

    def _run(self, command, *args, **kwargs):
        try:
            return command(*args, **kwargs)
        except self._redis.RedisError as error:
            raise StoreUnavailable(str(error)) from error

    def get(self, key):
        return self._run(self._client.get, key)

    def set(self, key, value, px=None, nx=False):
        return bool(self._run(self._client.set, key, value, px=px, nx=nx))  # None (NX refused) -> False

    def delete(self, key):
        self._run(self._client.delete, key)

    def incr(self, key):
        return self._run(self._client.incr, key)

    def delete_if_equal(self, key, value):
        return bool(self._run(self._release, keys=[key], args=[value]))
Some notes on it:
SETwithNXandPXis one atomic command.NXmeans "only if the key doesn't exist", andPXsets a lifetime in milliseconds. It's how we'll take locks. Redis marks the oldSETNXcommand as deprecated in favor ofSETwithNX.The Lua script comes from the Redis docs. It deletes a lock only if the value still matches your token, so you never delete someone else's lock. Redis 8.4 added
DELEX key IFEQ value, which does the same in one command. The script works everywhere, so I've used that.StoreUnavailableis the important part. Any Redis error turns into one exception type that the cache catches. A cache outage must never become an app outage.The timeouts are short on purpose. 100 ms is plenty for a cache. If Redis hangs, you want to give up and move on.
Now the cache itself. It has six ways to read, which we'll meet one at a time:
import json
import math
import random
import threading
import time
import uuid

from store import StoreUnavailable


def should_refresh_early(now, fresh_until, delta, beta, rand):
    """XFetch: the closer we get to expiry, the likelier a reader volunteers to refresh.
    `delta` is how long the last load took, `rand` is a random number in (0, 1]."""
    return now - delta * beta * math.log(rand) >= fresh_until


def in_a_thread(fn):
    threading.Thread(target=fn, daemon=True).start()


class Cache:
    def __init__(self, store, clock=time.time, sleep=time.sleep, rng=None):
        self.store, self.clock, self.sleep = store, clock, sleep
        self.rng = rng or (lambda: 1.0 - random.random())  # in (0, 1], so log() is always safe

    # ---- plumbing: a cache outage must never become an app outage -------------------------

    def _read(self, key):
        try:
            raw = self.store.get(key)
        except StoreUnavailable:
            return None
        return json.loads(raw) if raw is not None else None

    def _put(self, key, value, ttl, grace=0, delta=0.0, spread=0.1):
        ttl = ttl * (1 + spread * (2 * self.rng() - 1))  # jitter: +/- 10% so keys don't expire together
        entry = {"value": value, "fresh_until": self.clock() + ttl, "delta": delta}
        try:
            self.store.set(key, json.dumps(entry), px=int((ttl + grace) * 1000))
        except StoreUnavailable:
            pass

    def _load(self, key, loader, ttl, grace=0):
        started = self.clock()
        value = loader()
        self._put(key, value, ttl, grace, delta=self.clock() - started)
        return value

    def _acquire(self, key, ms):
        token = uuid.uuid4().hex
        return token if self.store.set(f"lock:{key}", token, px=ms, nx=True) else None

    def _release(self, key, token):
        try:
            self.store.delete_if_equal(f"lock:{key}", token)  # never deletes someone else's lock
        except StoreUnavailable:
            pass

    # ---- 1. cache-aside ----------------------------------------------------------------------

    def get_or_load(self, key, loader, ttl=300):
        entry = self._read(key)
        return entry["value"] if entry is not None else self._load(key, loader, ttl)

    def invalidate(self, key):
        try:
            self.store.delete(key)
        except StoreUnavailable:
            pass  # the TTL is the backstop

    # ---- 2. write-through: call it right after the database write succeeds --------------------

    def write_through(self, key, value, ttl=300):
        self._put(key, value, ttl)

    # ---- 3. generation keys: cache-aside without stale sets -----------------------------------

    def get_versioned(self, key, loader, ttl=300):
        try:
            generation = self.store.get(f"gen:{key}") or "0"  # read it BEFORE loading
        except StoreUnavailable:
            return loader()
        return self.get_or_load(f"{key}:g{generation}", loader, ttl)

    def invalidate_versioned(self, key):
        try:
            self.store.incr(f"gen:{key}")  # older entries become unreachable
        except StoreUnavailable:
            pass

    # ---- 4. one loader per key ---------------------------------------------------------------

    def get_locked(self, key, loader, ttl=300, grace=0, lock_ms=10_000, poll=0.05, max_wait=5.0):
        entry = self._read(key)
        if entry is not None:
            return entry["value"]

        give_up_at = self.clock() + max_wait
        while True:
            try:
                token = self._acquire(key, lock_ms)
            except StoreUnavailable:
                return loader()  # no cache, no coordination: just load
            if token:
                break
            entry = self._read(key)  # someone else is loading, so wait for their result
            if entry is not None:
                return entry["value"]
            if self.clock() >= give_up_at:
                return loader()  # waited long enough: do it ourselves
            self.sleep(poll)

        try:
            entry = self._read(key)  # it may have been filled while we were acquiring the lock
            return entry["value"] if entry is not None else self._load(key, loader, ttl, grace)
        finally:
            self._release(key, token)

    # ---- 5. serve stale data while one caller refreshes it -------------------------------------

    def get_swr(self, key, loader, ttl=60, grace=300, run=in_a_thread):
        entry = self._read(key)
        if entry is None:
            return self.get_locked(key, loader, ttl, grace)  # nothing cached at all
        if self.clock() < entry["fresh_until"]:
            return entry["value"]

        try:
            token = self._acquire(key, 30_000)
        except StoreUnavailable:
            token = None
        if token:  # stale: exactly one caller volunteers to refresh

            def refresh():
                try:
                    self._load(key, loader, ttl, grace)
                finally:
                    self._release(key, token)

            run(refresh)
        return entry["value"]  # everyone gets the stale value straight away

    # ---- 6. refresh a little early, at random (XFetch) ----------------------------------------

    def get_xfetch(self, key, loader, ttl=300, beta=1.0):
        entry = self._read(key)
        if entry is not None and not should_refresh_early(
            self.clock(), entry["fresh_until"], entry["delta"], beta, self.rng()
        ):
            return entry["value"]
        return self._load(key, loader, ttl)
Each entry is stored as a small JSON envelope: the value, when it stops being fresh, and how long the last load took. That extra bookkeeping is what lets the later patterns work.
Cache-aside
This is the one you'll use most. The app asks the cache first. On a miss it loads from the database and fills the cache.
flowchart TD
    A["Request for user:42"] --> B{"In Redis?"}
    B -->|"hit"| C["Return it"]
    B -->|"miss"| D["Load from the database"]
    D --> E["Store in Redis with a TTL"]
    E --> C
Using it takes one line:
cache = Cache(RedisStore())
user = cache.get_or_load("user:42", lambda: db.load_user(42), ttl=300)
The advantages are real. Only data that's actually requested gets cached, and a cache that's empty or down still returns correct answers, just more slowly. The AWS docs list two costs: each miss is slower than not caching at all, and data can go stale.
A few habits make it work better:
Always set a TTL. It's your safety net for every bug in your invalidation logic.
Jitter the TTL. The code randomizes each lifetime by plus or minus 10%, so keys loaded together don't all expire together.
Cache "not found" too. A
Noneresult is stored like any other. Without that, a request for something that doesn't exist hits the database every single time.Put the version in the key. When the shape of the data changes, change the key prefix. Old entries just age out.
Updating: delete, don't overwrite
When data changes, the usual advice is to delete the cache key and let the next read reload it. Overwriting the cached value in place has its own race: two writers can finish in the wrong order and leave the older value behind.
db.update_user(42, new_name)
cache.invalidate("user:42")   # database first, then delete
That's simple and almost always right. But there's one race it doesn't close.
The stale-set race
Here a reader and a writer overlap:
sequenceDiagram
    participant R as Reader
    participant C as Redis
    participant D as Database
    participant W as Writer
    R->>C: GET user:42 (miss)
    R->>D: SELECT user 42 (gets the old value)
    W->>D: UPDATE user 42 (new value)
    W->>C: DEL user:42
    R->>C: SET user:42 = old value
    Note over C: Stale until the TTL runs out
The reader loaded the old value, got delayed, and wrote it back after the writer's delete. The cache now holds stale data, and nothing will fix it until the TTL runs out.
The test test_cache_aside_with_delete_on_write_can_cache_a_stale_value reproduces this exactly, with two threads and a pair of events that force the order.
It's rare on any one request. At scale it happens every day. Facebook described this problem, and the thundering herd, in their Scaling Memcache at Facebook paper, and fixed both with leases. On a miss, the server hands out a token. A delete invalidates outstanding tokens, so a late writer's set is refused.
You can get a similar effect without server support, using generation keys:
user = cache.get_versioned("user:42", lambda: db.load_user(42))   # reads
cache.invalidate_versioned("user:42")                             # after a write
Instead of deleting the entry, a write bumps a counter. Readers look up the counter first, then use it in the key: user:42:g7. The late reader above stores its stale value under g0, but everyone now reads from g1, so it's never seen.
The order matters. The reader must read the counter before it loads from the database. The test test_generation_keys_survive_the_same_race runs the same interleaving and gets the new value.
The costs are one extra read per lookup, and one rule: the counter key must live at least as long as the longest entry TTL. If Redis evicts it, the counter restarts from zero and old entries could come back. Keep entry TTLs short as a backstop.
Write-through
Write-through updates the cache on every write, right after the database write succeeds:
db.update_user(42, new_name)                              # 1. the database is the source of truth
cache.write_through("user:42", db.load_user(42))          # 2. then the cache
The AWS docs sum up the trade: data in the cache is never stale, but every write now makes two trips. It also fills the cache with data nobody may ever read. Pairing it with cache-aside and a TTL fixes that, because anything missing just gets loaded on demand.
Do the database first. If it fails, nothing has changed. If you update the cache first and the database write then fails, you've cached something that never happened.
When the second write fails
There's no transaction spanning Redis and your database. If the cache update fails after the database commit, the cache is wrong.
The test test_if_the_cache_write_fails_the_ttl_is_the_backstop shows what happens: the stale value is served, then replaced once the TTL runs out. Your options are to retry, to delete the key instead, or to accept the staleness window. Whichever you choose, the TTL puts a ceiling on how wrong the cache can be.
In textbook write-through, the cache layer itself writes to the database. With Redis you usually do both writes in your own code. The behavior is the same, but the failure handling is yours.
The stampede problem
A cache stampede, also called a thundering herd or dogpile, goes like this. A popular key expires. Many requests arrive before anyone has reloaded it. Every one of them misses, and every one of them queries the database.
Here's a demo you can run. It fires 50 requests at the same instant, with an empty cache and a database that takes 200 ms:
from test_cache import stampede

for method in ("get_or_load", "get_locked", "get_swr"):
    reads, _ = stampede(method)
    print(f"{method:12s} -> {reads} database read(s) for 50 simultaneous requests")
The result:
get_or_load  -> 50 database read(s) for 50 simultaneous requests
get_locked   -> 1 database read(s) for 50 simultaneous requests
get_swr      -> 1 database read(s) for 50 simultaneous requests
Fifty identical queries for one answer. And it gets worse, because the database slows down under the load:
flowchart LR
    A["Hot key expires"] --> B["Many requests miss at once"]
    B --> C["All of them query the database"]
    C --> D["The database slows down"]
    D --> E["Each load takes longer"]
    E --> F["The miss window grows and more requests pile in"]
    F --> C
A slow load makes the window wider, which brings in more requests, which makes the load slower. That loop is how a single expired key becomes an outage.
Five defenses
Defense | How it works | What it costs | Best for |
|---|---|---|---|
TTL jitter | Randomize TTLs so keys don't expire together | Nothing | Many keys loaded at the same time |
Lock | One request loads, the rest wait for its result | Waiting, plus a lock to manage | Expensive loads where stale data isn't OK |
Stale-while-revalidate | Serve the old value while one request refreshes it | Slightly stale reads | Hot keys where freshness can slip |
XFetch | Readers randomly refresh a little before expiry | A few extra loads | The hottest keys, with no coordination |
Scheduled refresh | A background job refreshes known hot keys | A job to run | Keys you know are always hot |
You'll often combine two or three. Let's go through them.
1. TTL jitter
Already built in. If you load 10,000 keys at startup with a flat 300-second TTL, they all expire in the same second five minutes later. Plus or minus 10% spreads them over a minute.
It does nothing for a single hot key, though. For that you need one of the next four.
2. A lock, so only one request loads
user = cache.get_locked("user:42", lambda: db.load_user(42), ttl=300)The first request takes a lock with SET lock:user:42 <token> NX PX 10000. The rest poll the cache and pick up the result when it appears. In the demo above, that's 1 database read instead of 50.
The details that matter:
A random token per request. The lock holds a unique value, and release uses the compare-and-delete script. Otherwise a slow request could delete a lock that expired and was taken by someone else.
test_releasing_a_lock_never_deletes_someone_elseschecks it.A double-check after taking the lock. The value may have been filled while you waited. Without that check, the waiters you just held back all reload one after another. The test catches it.
Always release, even on failure. The
finallyblock frees the lock if the loader raises.A lock TTL. If a request crashes holding the lock, the TTL frees it. Set it longer than a normal load.
A way out. If the lock holder never finishes, waiters give up after
max_waitand load it themselves.
Is a Redis lock safe enough? For this, yes. Martin Kleppmann's well-known article splits locks into two kinds.
Locks for efficiency avoid doing the same work twice, and an occasional failure just wastes a little effort. Locks for correctness protect data from corruption, and those need much stronger guarantees.
A cache refresh lock is the first kind. If it fails and two requests load, you've lost nothing but a query.
3. Stale-while-revalidate
Some data can be slightly old without anyone noticing. So don't throw it away at expiry. Keep it for a grace period, and serve it while one request fetches a fresh copy:
product = cache.get_swr("product:7", lambda: db.load_product(7), ttl=60, grace=300)Each entry has two clocks. After ttl seconds it's stale. After ttl + grace seconds Redis actually removes it. A stale read returns the old value immediately, and one request, chosen with the same lock trick, refreshes it in the background.
Nobody waits. test_stale_while_revalidate_serves_stale_and_refreshes_exactly_once fires 50 requests at a stale key while the loader is blocked, and all 50 get the old value straight away. Then it releases the loader and checks that exactly one refresh happened.
The cold case, where nothing is cached at all, falls back to the lock. That's why the demo above shows 1 read for get_swr too.
4. XFetch: refresh a little early, at random
The first three defenses react after trouble starts, or at expiry. XFetch avoids expiry altogether. It comes from a 2015 VLDB paper by Vattani, Chierichetti and Lowenstein, Optimal Probabilistic Cache Stampede Prevention.
Every reader makes an independent random decision. The closer the key is to expiring, the likelier that reader volunteers to refresh it. The rule is one line:
refresh now if: now - delta * beta * ln(random) >= expirydelta is how long the last load took, so slow loads get refreshed earlier. beta is a dial, with 1.0 as the sensible default. random is a number between 0 and 1, so its logarithm is negative, which means the left side jumps ahead of "now" by a random amount.
The test test_xfetch_probability_matches_the_formula checks the maths. With one second left and a half-second load, the chance of a refresh should be exp(-1 / 0.5), about 13.5%. Over 100,000 draws it lands within half a percentage point of that.
Does it work? A simulation reads one hot key 50 times a second for 200 seconds. The TTL is 10 seconds and each load takes half a second:
Reads that found the key missing | Loads | |
|---|---|---|
Plain cache-aside | 20 | 20 |
XFetch | 1 | 24 |
The one miss for XFetch is the very first read, on an empty cache. After that, a volunteer always refreshed the key before it expired. The price is about four extra loads over 200 seconds.
Each of the 20 misses in the plain run is a stampede waiting to happen. At 50 reads a second and half-second loads, up to about 25 requests would miss together every time.
XFetch is probabilistic, so it isn't a guarantee. Under heavy concurrency two readers can still volunteer at once. It's best on its own for the very hottest keys, or combined with a lock.
5. Scheduled refresh
If you know which keys are always hot, like a home page or a pricing table, don't let them expire. A background job refreshes them on a timer, a bit shorter than the TTL.
There's no code to show, because it's just a cron job calling your loader and write_through. The catch is that you have to know the hot keys in advance.
Redis settings that matter
Caching code is half the job. The server has to be set up like a cache:
Set
maxmemoryand an eviction policy. The Redis docs suggestallkeys-lruas a good default if you have no reason to prefer another. It evicts the least recently used keys, whether or not they have a TTL.Beware the
volatile-*policies. They only evict keys that have a TTL, and they behave likenoevictionif none do. Fill the server with keys that never expire and writes start failing.Measure your hit rate.
INFO statsreportskeyspace_hitsandkeyspace_misses. The hit rate ishits / (hits + misses).Watch
evicted_keys. A rising count with a falling hit rate means the cache is too small, or the wrong policy is evicting your hot keys.Fail open, and fail fast. The
RedisStorehas a 100 ms timeout, andCachetreats an outage as a miss.test_a_cache_outage_falls_back_to_the_databasechecks that nothing raises when the store is down.Remember what an outage means. With Redis down, every request goes to the database. That's a stampede by definition, so think about load shedding or a circuit breaker for your database.
Don't use
KEYSin production. It scans every key. UseSCAN.
Which one do you need?
flowchart TD
    A["What are you caching?"] --> B{"Can readers see old data for a short while?"}
    B -->|"Yes"| C["Cache-aside with a TTL, and delete on write"]
    B -->|"Rarely"| D["Add write-through, or generation keys"]
    C --> E{"Is any key very hot or slow to load?"}
    D --> E
    E -->|"Yes"| F["Add stale-while-revalidate or a lock, and XFetch for the hottest"]
    E -->|"No"| G["TTL jitter is enough"]
Try it against real Redis
The tests use the in-memory stand-in. Once you have a Redis server, a quick check that the real adapter works:
from cache import Cache
from store import RedisStore

cache = Cache(RedisStore())  # defaults to redis://localhost:6379/0
print(cache.get_locked("smoke:1", lambda: "hello", ttl=30))
It should print hello. Then redis-cli GET smoke:1 shows the JSON envelope the cache stored.
The tests
The stand-in is a small fake that behaves like Redis for the five operations we use. Atomic commands, NX refusing existing keys, expiry, INCR keeping the TTL, and compare-and-delete:
import threading
import time
from collections import Counter

from store import StoreUnavailable


class FakeClock:
    def __init__(self, now=1_000_000.0):
        self.now = now

    def __call__(self):
        return self.now

    def advance(self, seconds):
        self.now += seconds


class FakeStore:
    """An in-memory stand-in with Redis's semantics for the five commands the cache uses:
    SET with NX and PX, GET, DEL, INCR, and compare-and-delete. Each command is atomic."""

    def __init__(self, clock=time.time):
        self.clock, self.down = clock, False
        self.commands = Counter()
        self._data, self._lock = {}, threading.Lock()

    def _enter(self, name):
        if self.down:
            raise StoreUnavailable("connection refused")
        self.commands[name] += 1
        self._lock.acquire()

    def _live(self, key):  # an expired key behaves as if it was never there
        item = self._data.get(key)
        if item and item[1] is not None and item[1] <= self.clock():
            del self._data[key]
            return None
        return item

    def get(self, key):
        self._enter("get")
        try:
            item = self._live(key)
            return item[0] if item else None
        finally:
            self._lock.release()

    def set(self, key, value, px=None, nx=False):
        self._enter("set")
        try:
            if nx and self._live(key):
                return False  # Redis replies nil
            self._data[key] = (value, self.clock() + px / 1000 if px else None)
            return True
        finally:
            self._lock.release()

    def delete(self, key):
        self._enter("delete")
        try:
            self._data.pop(key, None)
        finally:
            self._lock.release()

    def incr(self, key):
        self._enter("incr")
        try:
            item = self._live(key)
            number = int(item[0]) + 1 if item else 1
            self._data[key] = (str(number), item[1] if item else None)  # INCR keeps the TTL
            return number
        finally:
            self._lock.release()

    def delete_if_equal(self, key, value):
        self._enter("delete_if_equal")
        try:
            item = self._live(key)
            if item and item[0] == value:
                del self._data[key]
                return True
            return False
        finally:
            self._lock.release()
And the tests. They use real threads for the races and stampedes, and a fake clock wherever time needs to pass:
import json
import random
import threading
import time

from cache import Cache, should_refresh_early
from fake_store import FakeClock, FakeStore


def make(**kwargs):
    clock = FakeClock()
    store = FakeStore(clock)
    return Cache(store, clock=clock, sleep=clock.advance, **kwargs), store, clock


class Counter:
    """A loader that remembers how often it was called."""

    def __init__(self, value="v1"):
        self.value, self.calls = value, 0

    def __call__(self):
        self.calls += 1
        return self.value


# ---- cache-aside ------------------------------------------------------------------------------

def test_cache_aside_loads_once_then_hits_until_the_ttl_runs_out():
    cache, _, clock = make()
    load = Counter()
    assert [cache.get_or_load("k", load, ttl=60) for _ in range(3)] == ["v1"] * 3
    assert load.calls == 1
    clock.advance(70)  # even with +10% jitter, 60 seconds is long gone
    cache.get_or_load("k", load, ttl=60)
    assert load.calls == 2


def test_a_missing_value_is_cached_too():
    cache, _, _ = make()
    load = Counter(value=None)
    assert cache.get_or_load("nobody", load) is None and cache.get_or_load("nobody", load) is None
    assert load.calls == 1  # asking for something that doesn't exist doesn't hammer the database


def test_ttls_are_jittered_by_ten_percent():
    for rand, expected in ((1.0, 330), (1e-9, 270)):
        cache, store, clock = make(rng=lambda: rand)
        cache.get_or_load("k", Counter(), ttl=300)
        left = json.loads(store.get("k"))["fresh_until"] - clock.now
        assert abs(left - expected) < 0.01


def test_a_cache_outage_falls_back_to_the_database():
    cache, store, _ = make()
    store.down = True
    load = Counter()
    assert cache.get_or_load("k", load) == "v1" and cache.get_locked("k", load) == "v1"
    cache.write_through("k", "v2")
    cache.invalidate("k")  # none of this raises


# ---- write-through ------------------------------------------------------------------------------

def test_write_through_serves_the_new_value_without_asking_the_database():
    cache, _, _ = make()
    db = {"u": "old"}
    load = lambda: db["u"]
    assert cache.get_or_load("u", load) == "old"
    db["u"] = "new"
    cache.write_through("u", db["u"])  # database first, then the cache
    reads = Counter(value="should not be called")
    assert cache.get_or_load("u", reads) == "new" and reads.calls == 0


def test_if_the_cache_write_fails_the_ttl_is_the_backstop():
    cache, store, clock = make()
    db = {"u": "old"}
    load = lambda: db["u"]
    cache.get_or_load("u", load, ttl=60)
    db["u"] = "new"
    store.down = True
    cache.write_through("u", "new")  # the database write worked, the cache update didn't
    store.down = False
    assert cache.get_or_load("u", load) == "old"  # stale...
    clock.advance(70)
    assert cache.get_or_load("u", load) == "new"  # ...but only until the TTL runs out


# ---- the stale-set race ---------------------------------------------------------------------------

def race(read_through_cache, invalidate):
    """A reader loads the old value, a writer updates and invalidates, then the reader writes its stale value back."""
    db = {"u": "old"}
    loaded, proceed = threading.Event(), threading.Event()

    def slow_loader():
        value = db["u"]  # the reader sees "old"
        loaded.set()
        proceed.wait(5)  # ...and gets stuck for a moment
        return value

    reader = threading.Thread(target=lambda: read_through_cache("u", slow_loader))
    reader.start()
    loaded.wait(5)
    db["u"] = "new"  # the writer updates the database
    invalidate("u")  # and invalidates the cache, before the reader has stored anything
    proceed.set()
    reader.join()
    return read_through_cache("u", lambda: db["u"])  # what does the next reader see?


def test_cache_aside_with_delete_on_write_can_cache_a_stale_value():
    cache, _, _ = make()
    assert race(cache.get_or_load, cache.invalidate) == "old"  # stale until the TTL runs out


def test_generation_keys_survive_the_same_race():
    cache, _, _ = make()
    assert race(cache.get_versioned, cache.invalidate_versioned) == "new"


# ---- the stampede -------------------------------------------------------------------------------------

def stampede(method, threads=50, delay=0.2):
    """`threads` requests arrive at the same instant, with nothing in the cache."""
    cache, _, _ = make()
    cache.clock, cache.sleep = time.time, time.sleep  # real threads need real time
    loads, lock, barrier, results = [], threading.Lock(), threading.Barrier(threads), []

    def slow_loader():
        time.sleep(delay)
        with lock:
            loads.append(1)
        return "fresh"

    def request():
        barrier.wait()
        results.append(getattr(cache, method)("hot", slow_loader))

    workers = [threading.Thread(target=request) for _ in range(threads)]
    for w in workers:
        w.start()
    for w in workers:
        w.join()
    return len(loads), results


def test_without_protection_every_request_hits_the_database():
    loads, results = stampede("get_or_load")
    assert loads >= 45 and set(results) == {"fresh"}


def test_with_a_lock_only_one_request_hits_the_database():
    loads, results = stampede("get_locked")
    assert loads == 1 and results == ["fresh"] * 50


def test_the_lock_is_released_when_the_load_finishes_and_when_it_fails():
    cache, store, _ = make()
    cache.get_locked("k", Counter())
    assert store.get("lock:k") is None

    def broken():
        raise RuntimeError("database down")

    try:
        cache.get_locked("other", broken)
        raise AssertionError("the error should have been raised")
    except RuntimeError:
        assert store.get("lock:other") is None  # a failed load doesn't leave the key locked


def test_a_waiter_stops_waiting_when_the_lock_holder_never_finishes():
    cache, store, _ = make()
    cache.clock, cache.sleep = time.time, time.sleep
    store.set("lock:k", "someone-who-crashed", px=60_000)
    load = Counter()
    assert cache.get_locked("k", load, max_wait=0.2, poll=0.02) == "v1" and load.calls == 1


def test_releasing_a_lock_never_deletes_someone_elses():
    cache, store, clock = make()

    def slow_loader():
        clock.advance(11)  # we took longer than the 10-second lock
        store.set("lock:k", "second-holder", px=10_000, nx=True)  # so someone else took it
        return "v1"

    cache.get_locked("k", slow_loader, lock_ms=10_000)
    assert store.get("lock:k") == "second-holder"


def test_stale_while_revalidate_serves_stale_and_refreshes_exactly_once():
    cache, _, clock = make()
    cache.get_swr("hot", lambda: "stale", ttl=60)  # warm the key
    clock.advance(100)  # now past its freshness, but still in the cache
    gate, loads, refreshers = threading.Event(), [], []

    def loader():
        loads.append(1)
        gate.wait(5)
        return "fresh"

    def run(fn):
        refreshers.append(threading.Thread(target=fn))
        refreshers[-1].start()

    results = []
    workers = [threading.Thread(target=lambda: results.append(cache.get_swr("hot", loader, ttl=60, run=run))) for _ in range(50)]
    for w in workers:
        w.start()
    for w in workers:
        w.join()

    assert results == ["stale"] * 50  # nobody waited: the refresh is still blocked on the gate
    gate.set()
    for r in refreshers:
        r.join()
    assert len(loads) == 1 and len(refreshers) == 1
    assert cache.get_swr("hot", loader, ttl=60) == "fresh"


def test_stale_while_revalidate_cold_start_loads_once():
    loads, results = stampede("get_swr")
    assert loads == 1 and results == ["fresh"] * 50


# ---- XFetch ---------------------------------------------------------------------------------------------

def test_xfetch_probability_matches_the_formula():
    rng, draws = random.Random(1), 100_000
    # 1 second left, a load that takes 0.5s, beta 1: probability is exp(-1 / 0.5) = 13.5%
    hits = sum(should_refresh_early(0, 1.0, 0.5, 1.0, 1.0 - rng.random()) for _ in range(draws))
    assert abs(hits / draws - 0.1353) < 0.005
    assert should_refresh_early(2.0, 1.0, 0.5, 1.0, 1.0)  # past expiry: always
    assert not any(should_refresh_early(0, 100.0, 0.5, 1.0, 1.0 - rng.random()) for _ in range(draws))  # far away: never


def simulate(method, seconds=200, rate=50, ttl=10, load_time=0.5):
    """One hot key read `rate` times a second. Returns (reads that found nothing, total loads)."""
    rng = random.Random(7)
    cache, store, clock = make(rng=lambda: 1.0 - rng.random())
    loads = [0]

    def loader():
        loads[0] += 1
        clock.advance(load_time)  # loading takes a while
        return loads[0]

    empty = 0
    for _ in range(seconds * rate):
        empty += store.get("hot") is None
        getattr(cache, method)("hot", loader, ttl=ttl)
        clock.advance(1 / rate)
    return empty, loads[0]


def test_xfetch_refreshes_before_the_key_expires():
    plain_empty, plain_loads = simulate("get_or_load")
    early_empty, early_loads = simulate("get_xfetch")
    assert plain_empty >= 15  # one empty read per expiry: in real life, a stampede each time
    assert early_empty <= 3
    assert early_loads <= plain_loads * 1.3  # the price: a few extra loads


# ---- the stand-in itself ---------------------------------------------------------------------------------

def test_the_fake_store_behaves_like_redis_for_the_commands_we_use():
    clock = FakeClock()
    store = FakeStore(clock)
    assert store.set("k", "a", px=1000, nx=True) is True
    assert store.set("k", "b", px=1000, nx=True) is False and store.get("k") == "a"  # NX refuses
    clock.advance(1.5)
    assert store.get("k") is None and store.set("k", "c", nx=True) is True  # expired keys are gone
    assert store.incr("n") == 1 and store.incr("n") == 2
    assert store.delete_if_equal("k", "wrong") is False and store.get("k") == "c"
    assert store.delete_if_equal("k", "c") is True and store.get("k") is None
Run them with pytest -q. They check the caching logic, not Redis itself. The fake follows the documented Redis behavior, but only a real server proves your configuration, so run the smoke check above and watch your hit rate in production.
In short
Cache-aside for reads, delete on write, and always a TTL.
Overlapping reads and writes can leave stale data behind. Generation keys or leases close that gap.
Write-through keeps the cache fresh at the price of slower writes. The second write can still fail.
A stampede turns one expired key into many database queries. A lock, stale-while-revalidate and XFetch each stop it in a different way.
Treat Redis as optional. Short timeouts and fall back to the database.
Details checked against the Redis documentation, the AWS ElastiCache docs and the papers below on October 29, 2026. Commands and defaults change between Redis versions, so confirm them on the version you run.
Sources
Comments(0)
Join the discussion by logging into your account.
No comments yet. Be the first to comment!