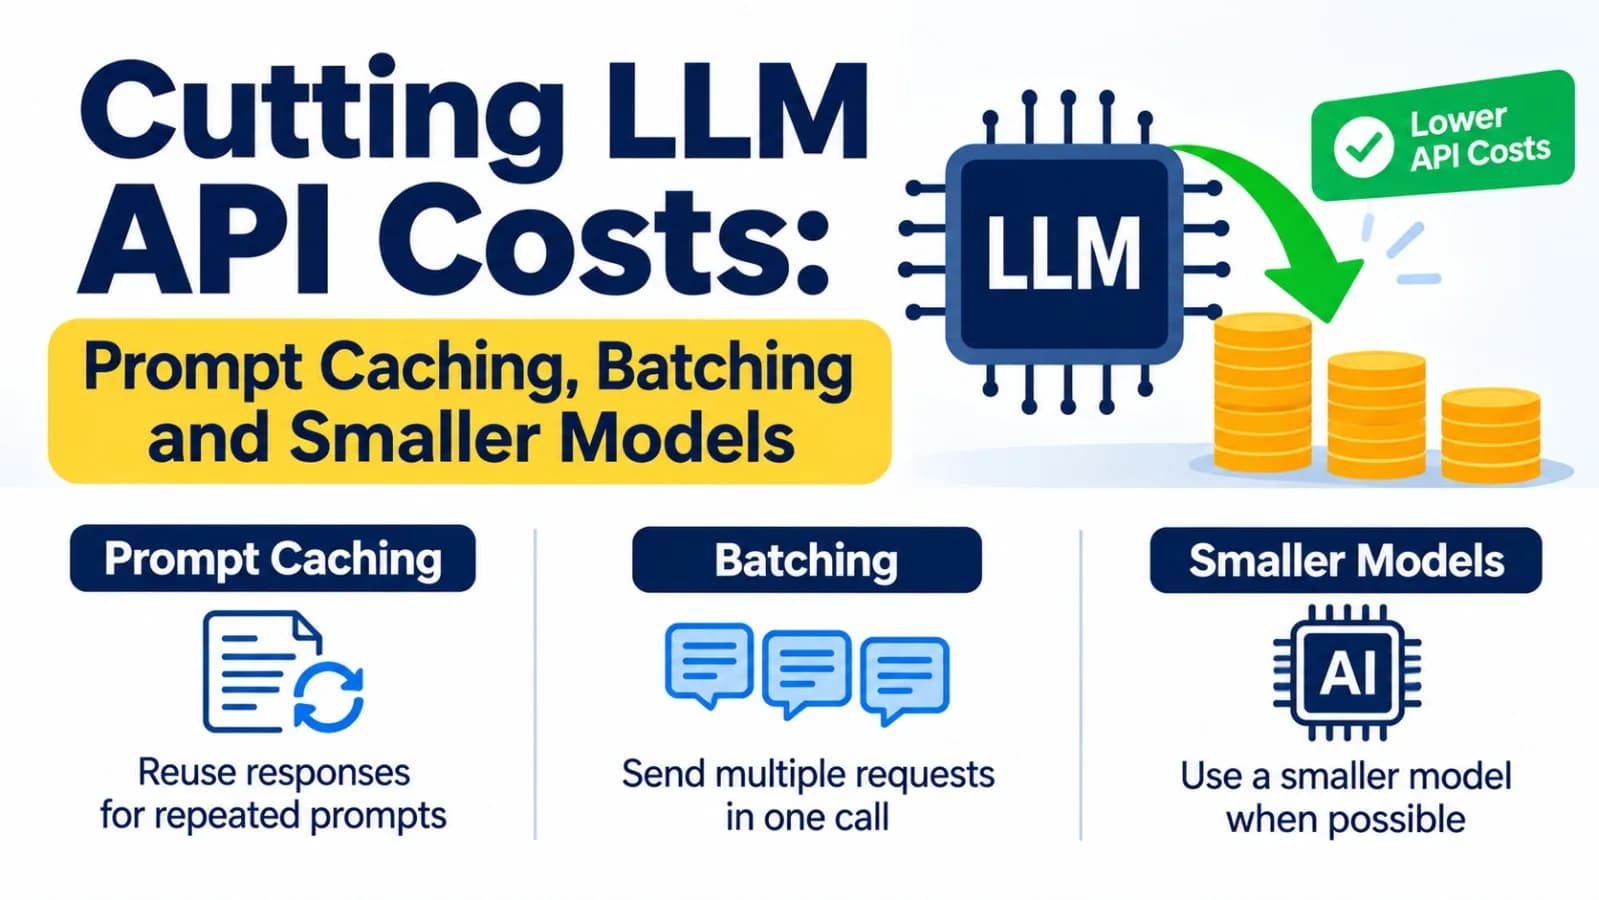
Cutting LLM API Costs: Prompt Caching, Batching and Smaller Models
An LLM bill grows faster than traffic. Here's how prompt caching, the Batch API and smaller models cut it, with real prices, tested Python c...
Nov 5, 2026
17 min
An LLM bill grows faster than traffic. Here's how prompt caching, the Batch API and smaller models cut it, with real prices, tested Python c...
Prompt caching can cut repeated input costs by around 80%, but only if your prompt is ordered so the stable parts come first. Here's how it ...
OpenAI cut GPT-6 Sol and Luna prices in half, improved caching for agent workloads, and published alignment numbers worth reading before gra...
Most developers think token optimization means shorter prompts. In 2026, the biggest costs come from bloated chat history, unused tool schem...
