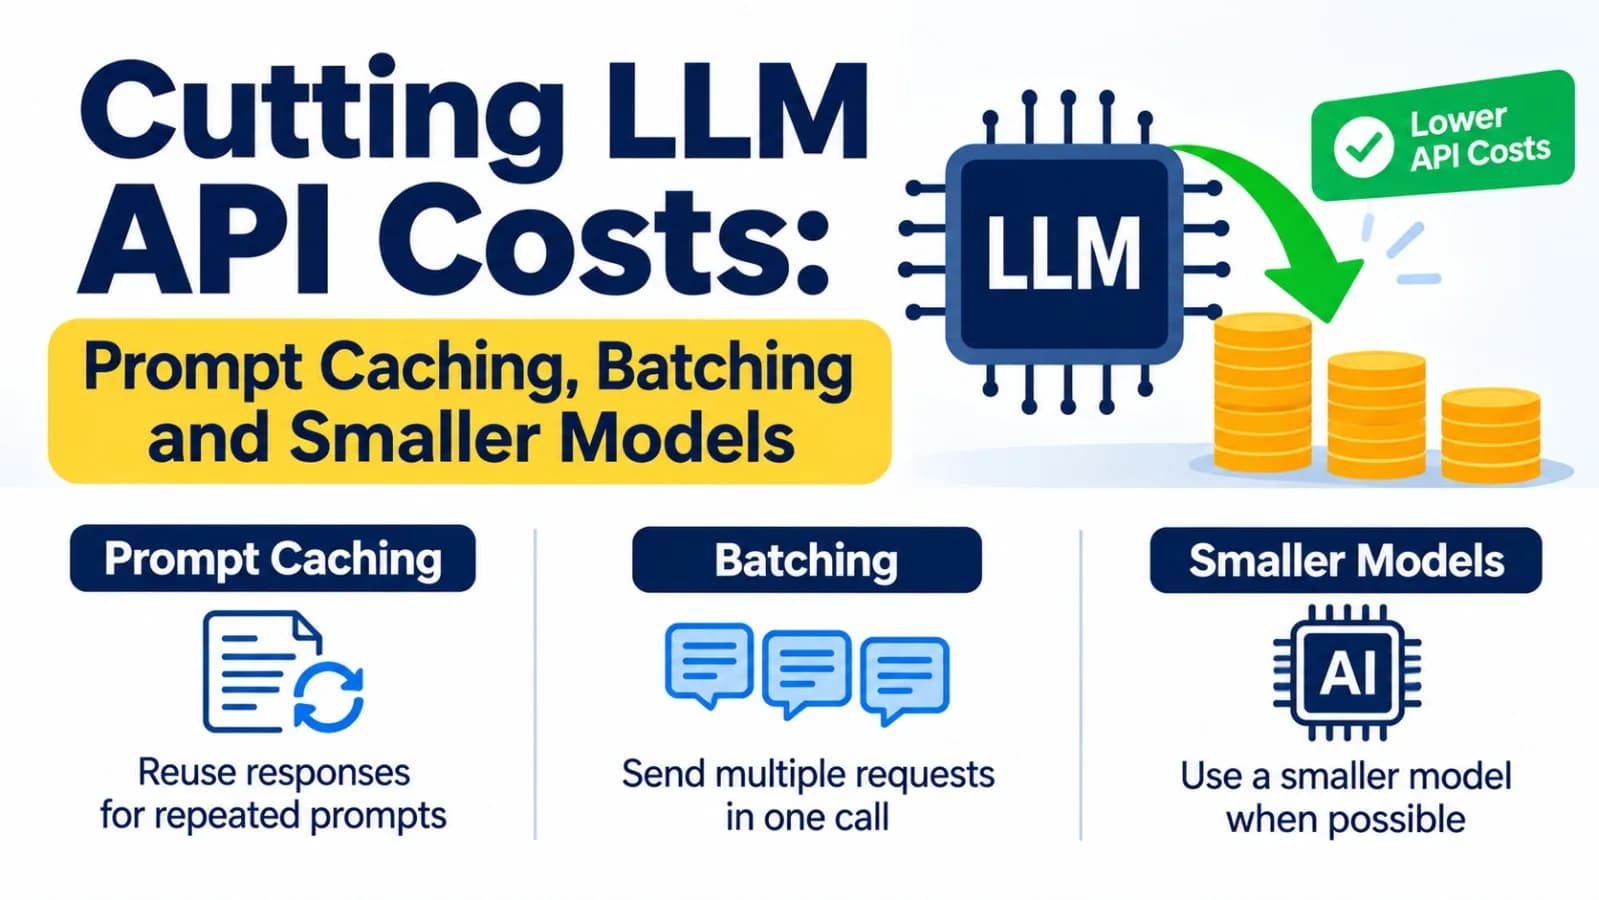
Cutting LLM API Costs: Prompt Caching, Batching and Smaller Models
An LLM bill grows faster than traffic. Here's how prompt caching, the Batch API and smaller models cut it, with real prices, tested Python c...
Nov 5, 2026
17 min
An LLM bill grows faster than traffic. Here's how prompt caching, the Batch API and smaller models cut it, with real prices, tested Python c...
Anthropic locked minors out of Claude.ai and got the enforcement wrong more than once along the way. None of that applies to what you build ...
AI agents are often overcomplicated. At their core, they’re just models that can call tools, use the results, and continue working. This tut...

Most developers think token optimization means shorter prompts. In 2026, the biggest costs come from bloated chat history, unused tool schem...
