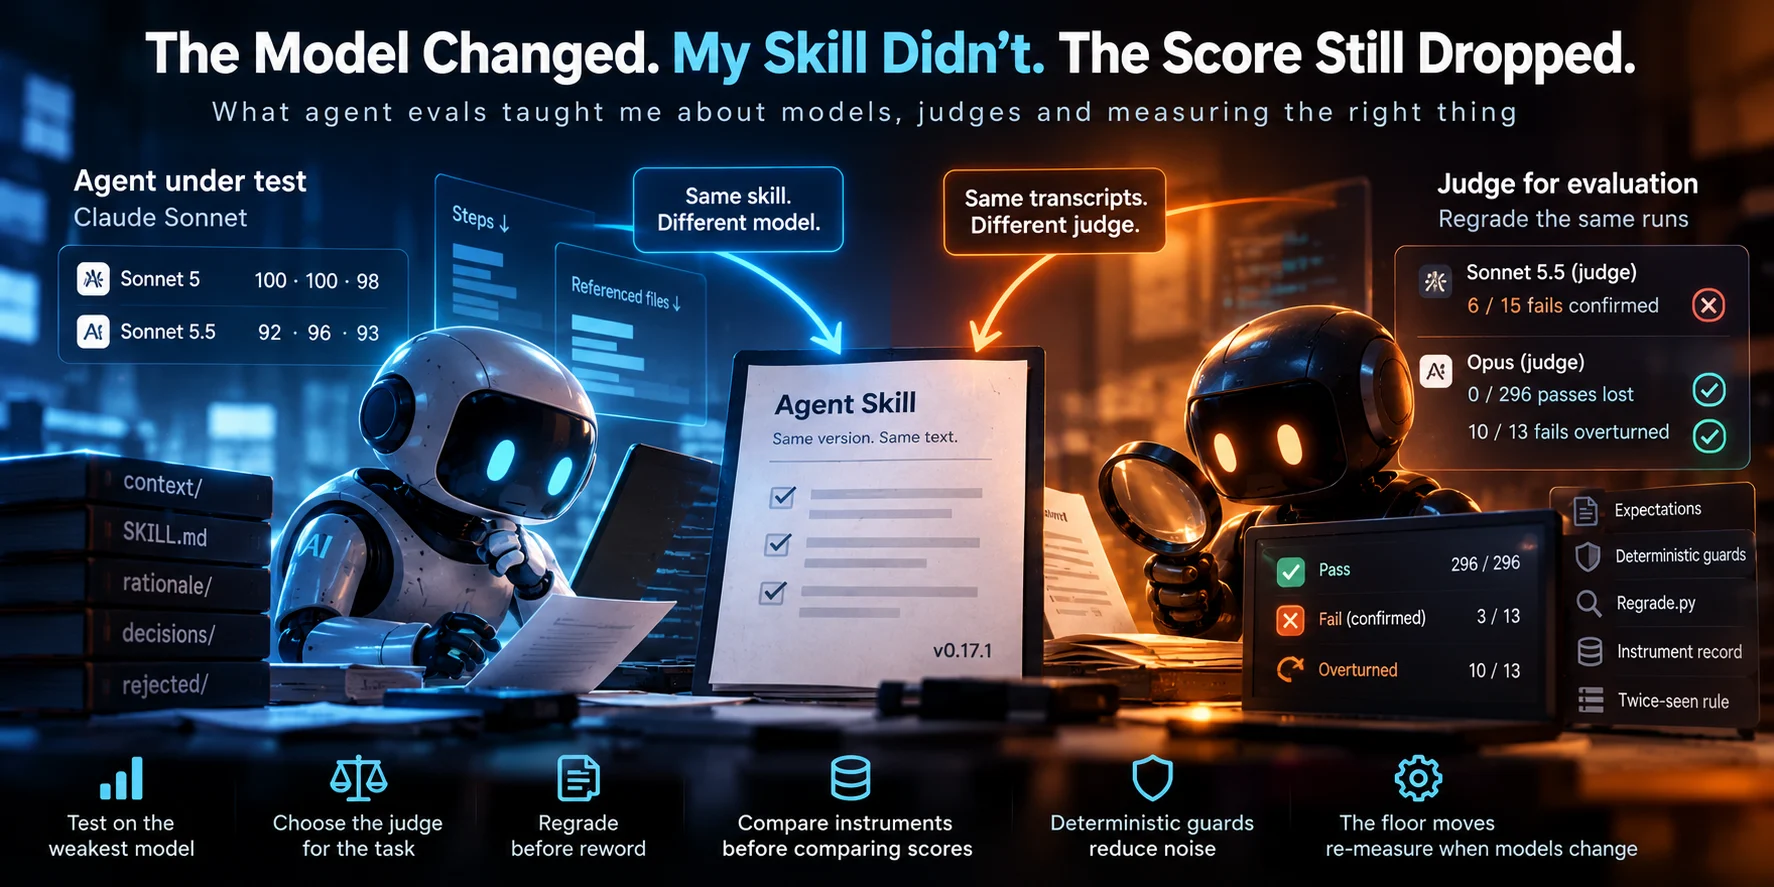
The Model Changed. My Skill Didn't. The Score Still Dropped.
My rule for evaluating an agent skill is deliberately asymmetric: Test the agent on the weakest model you intend to support. Choose the judg...
Oct 7, 2026
7 min
My rule for evaluating an agent skill is deliberately asymmetric: Test the agent on the weakest model you intend to support. Choose the judg...
Strata runs a 125-billion-parameter AI model on a normal Windows or Linux PC with a 12 GB+ NVIDIA or AMD card. I read through the repo and d...
Gemini 4 Argon is Google’s new frontier model, leading on knowledge work, long-context reasoning and several benchmarks. But coding is mixed...
What happened I have a little Werewolf text game with LLMs. With a caveat - there is a role-play. Each game has a theme, a lore, a topic - a...

Jev is a “System One Model” that returns typed, calibrated probabilities for predefined question types in a single forward pass, enabling fa...

An international collaborative work 🎌 Introduction At the start of the year, I...

Most prompt books optimize for better answers. I wanted prompts that fail visibly. Most prompt...


Implementing a didactical ‘water marking’ sample application (for self learning and...
I was making a slide in Google Slides recently when a small button appeared at the bottom: Beautify the slide.
