
MLX: Machine Learning Built for Apple Silicon
Discover how Apple's MLX framework brings efficient machine learning to Apple silicon. Learn about unified memory, lazy evaluation, GPU acce...

Oct 22, 2026
6 min
Discover how Apple's MLX framework brings efficient machine learning to Apple silicon. Learn about unified memory, lazy evaluation, GPU acce...
I use LLMs every day without knowing how they work, so I built the smallest one I could: a tiny transformer that writes Shakespeare one char...

Everyone seems to define the AI engineer job differently. This post explains what the role really involves, how it compares to ML engineer, ...
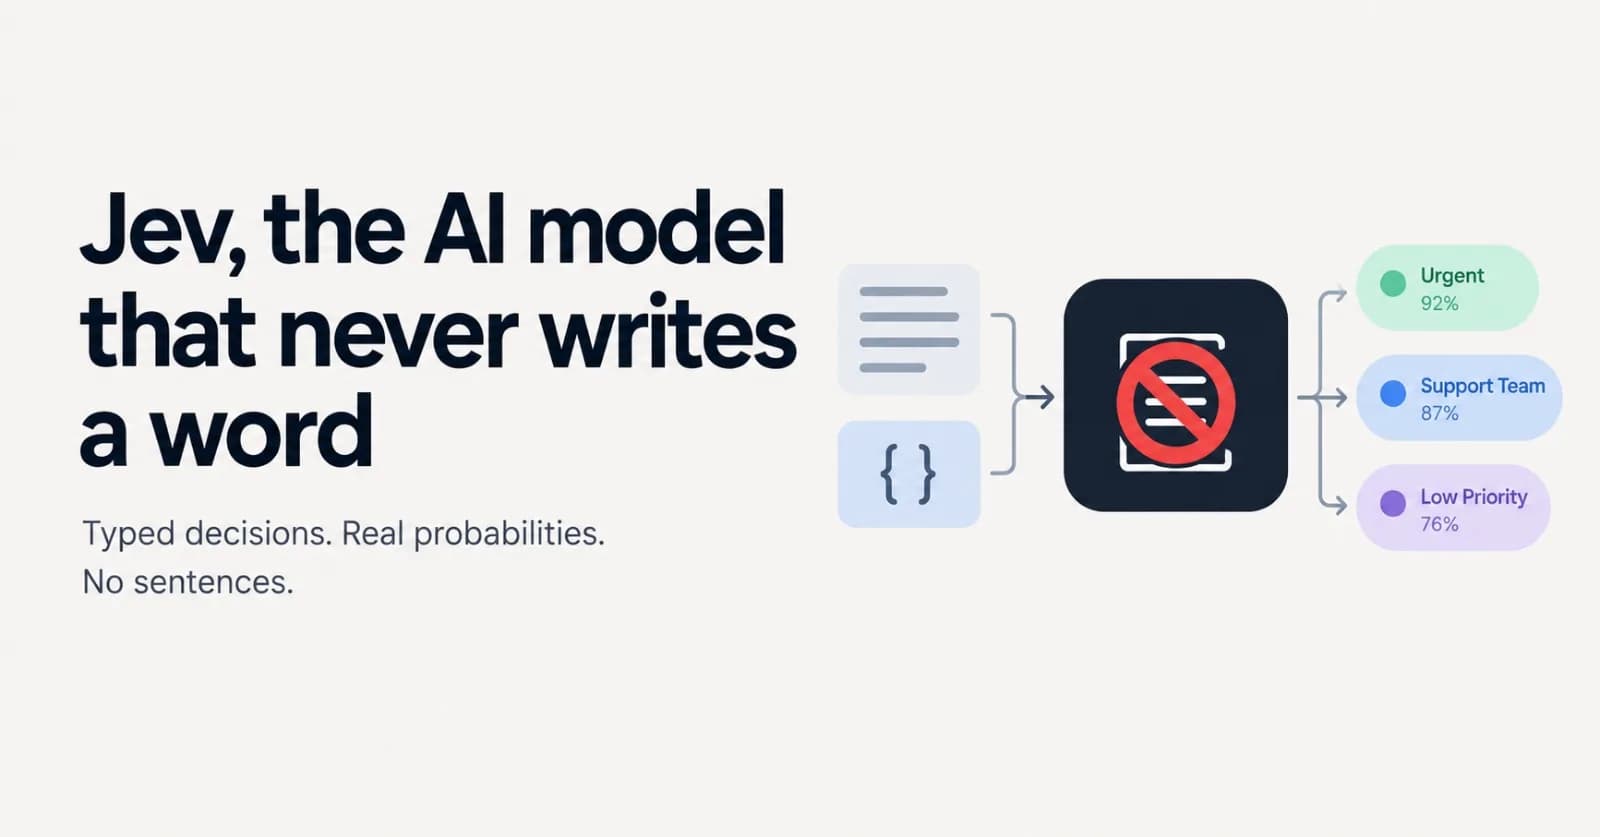
TypeSafe AI's Jev never writes a sentence. It answers typed questions in one parallel pass, with a probability on every answer. Here is how ...
Part 3 of our Neural Network Series: why depth alone doesn't help without activation functions, how sigmoid and ReLU work in plain language,...
Laya brings fast, structured decision-making to AI workflows with typed outputs for classification, scoring, and yes/no predictions. This de...
Most language models are trained once and frozen forever. mini-AGI is a small byte-level model that keeps learning continuously on a single ...
DeepSeek V4.1 Flash isn't just another model release. Its architecture, tiny KV cache, aggressive pricing, and retirement of V4-Pro point to...

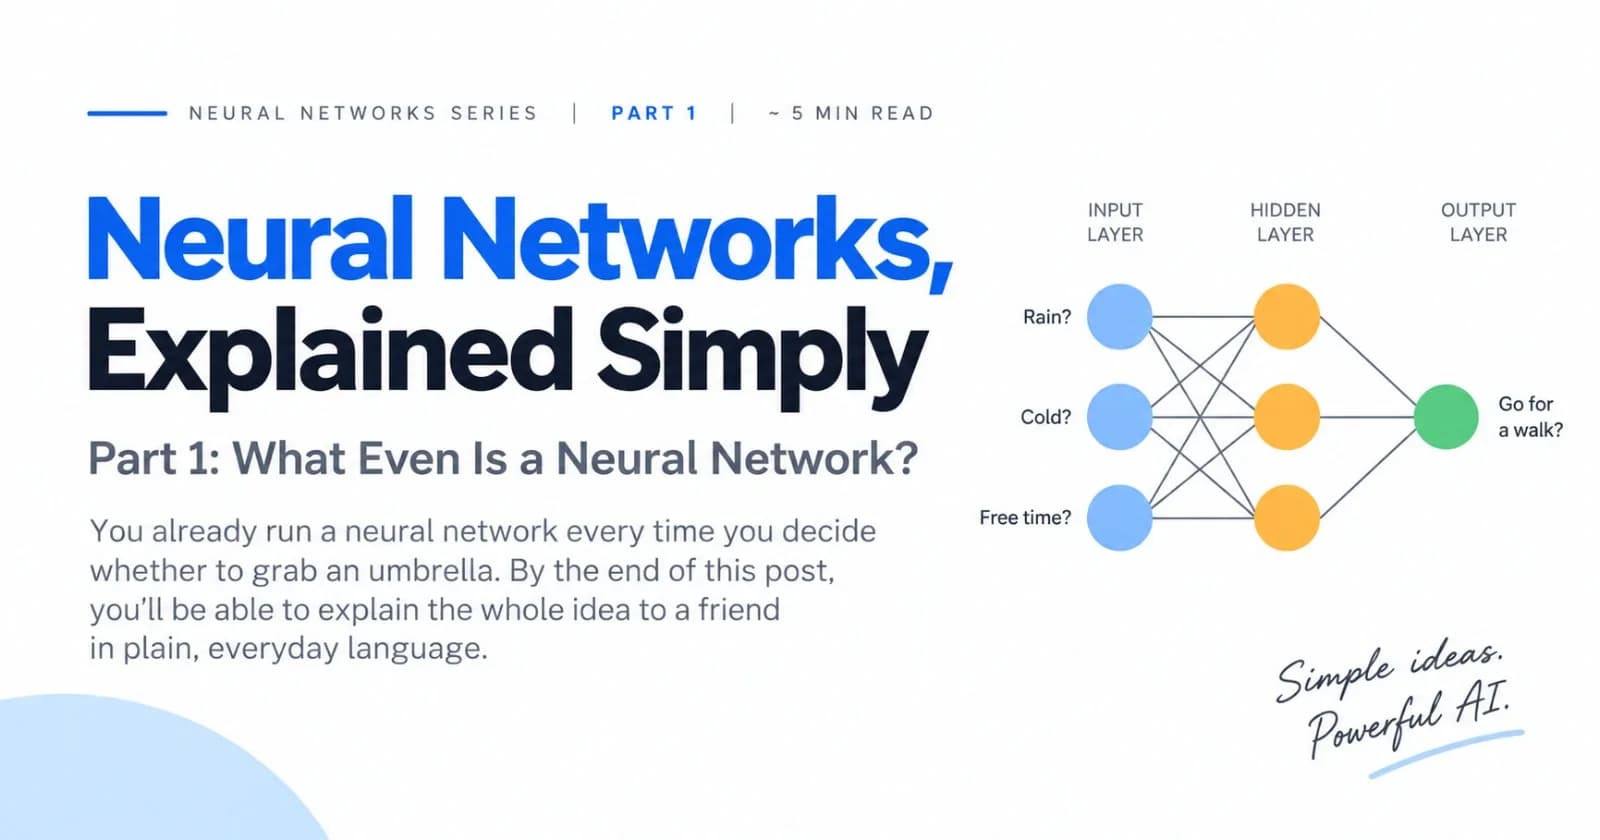
The first post in our Neural Network Series: how a single artificial neuron works, built from an everyday decision, then stacked into a full...