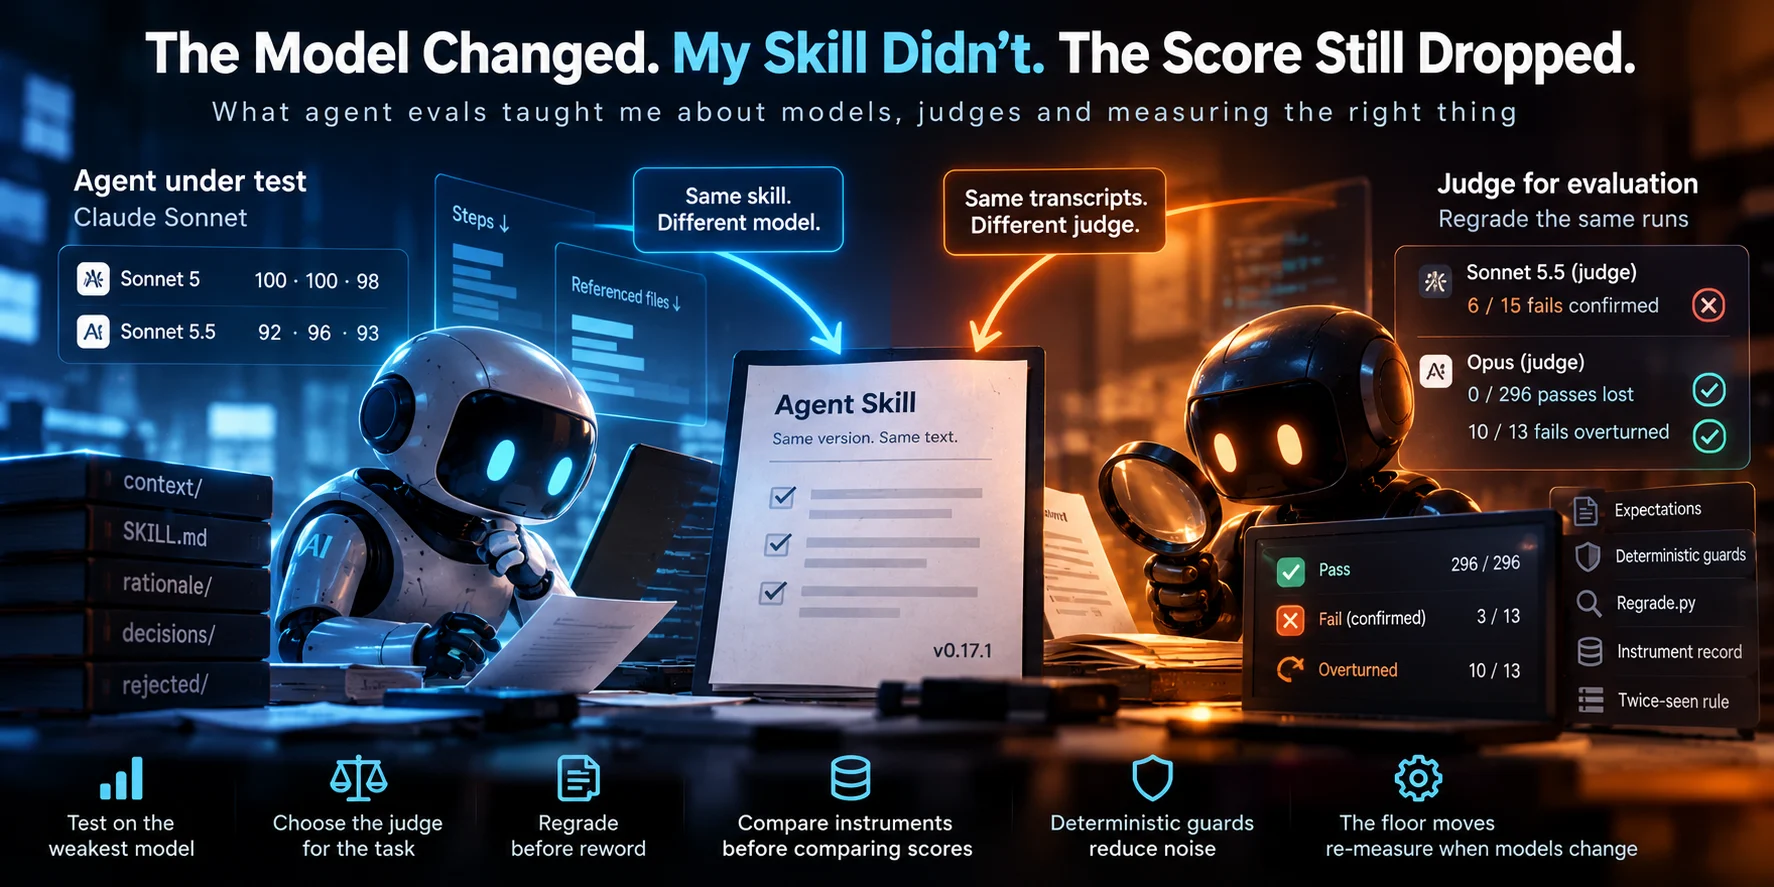
The Model Changed. My Skill Didn't. The Score Still Dropped.
My rule for evaluating an agent skill is deliberately asymmetric: Test the agent on the weakest model you intend to support. Choose the judg...
Oct 7, 2026
7 min
My rule for evaluating an agent skill is deliberately asymmetric: Test the agent on the weakest model you intend to support. Choose the judg...
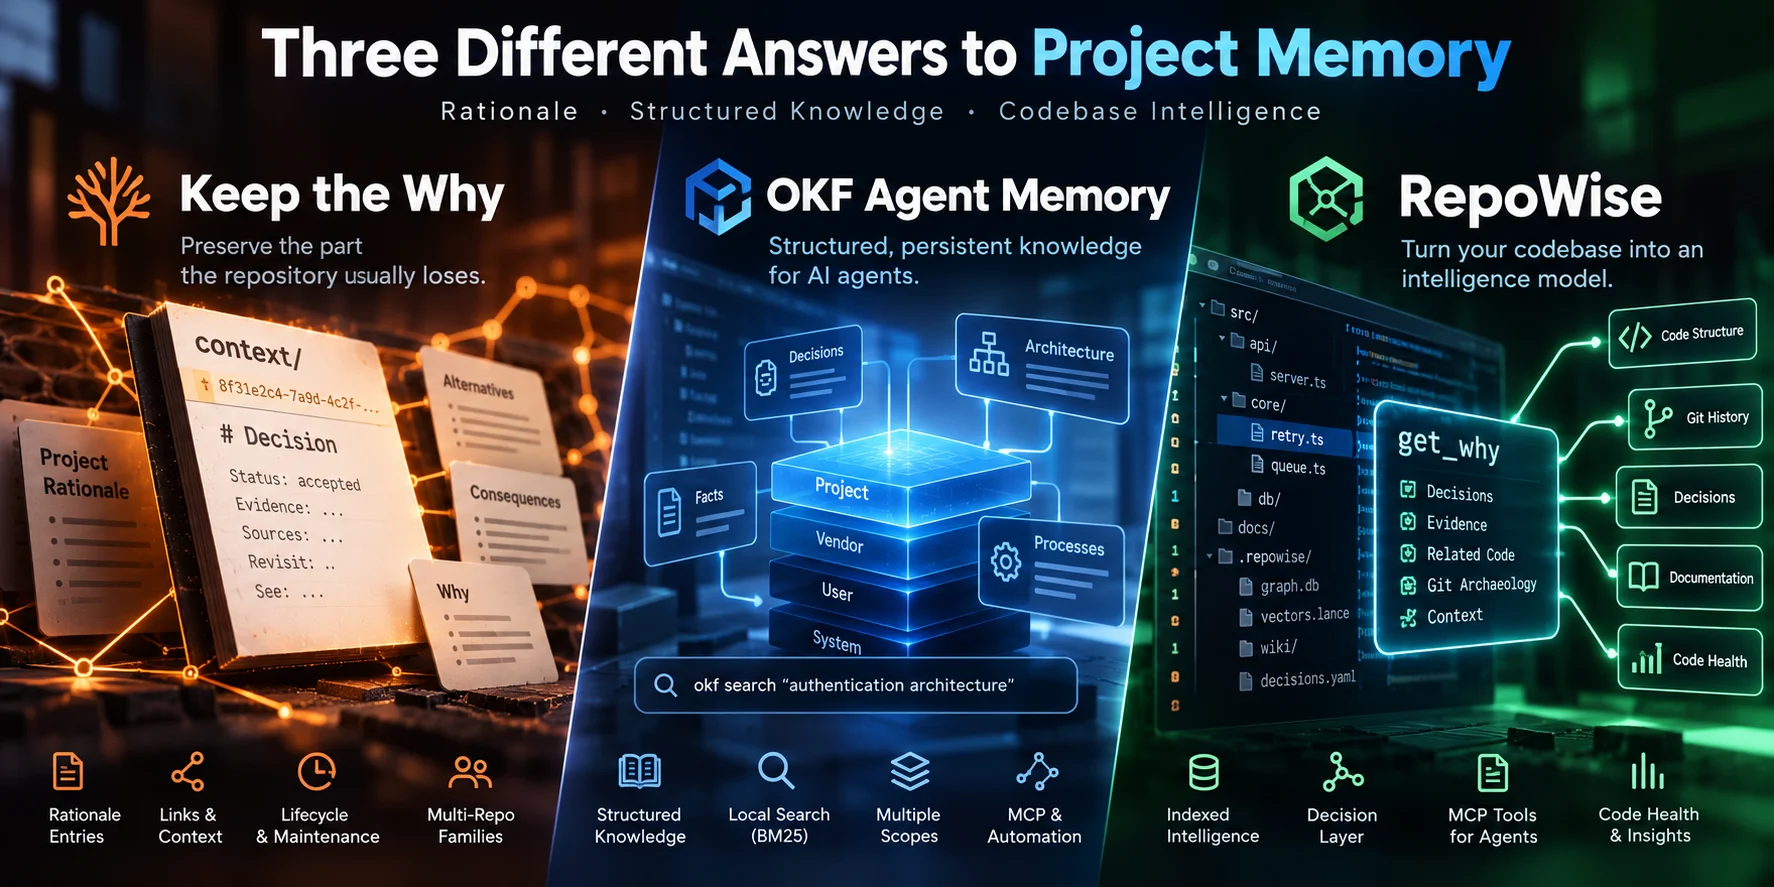
Three approaches to Git-native project memory for coding agents "Project memory for coding agents" is becoming a broad category. Three proje...
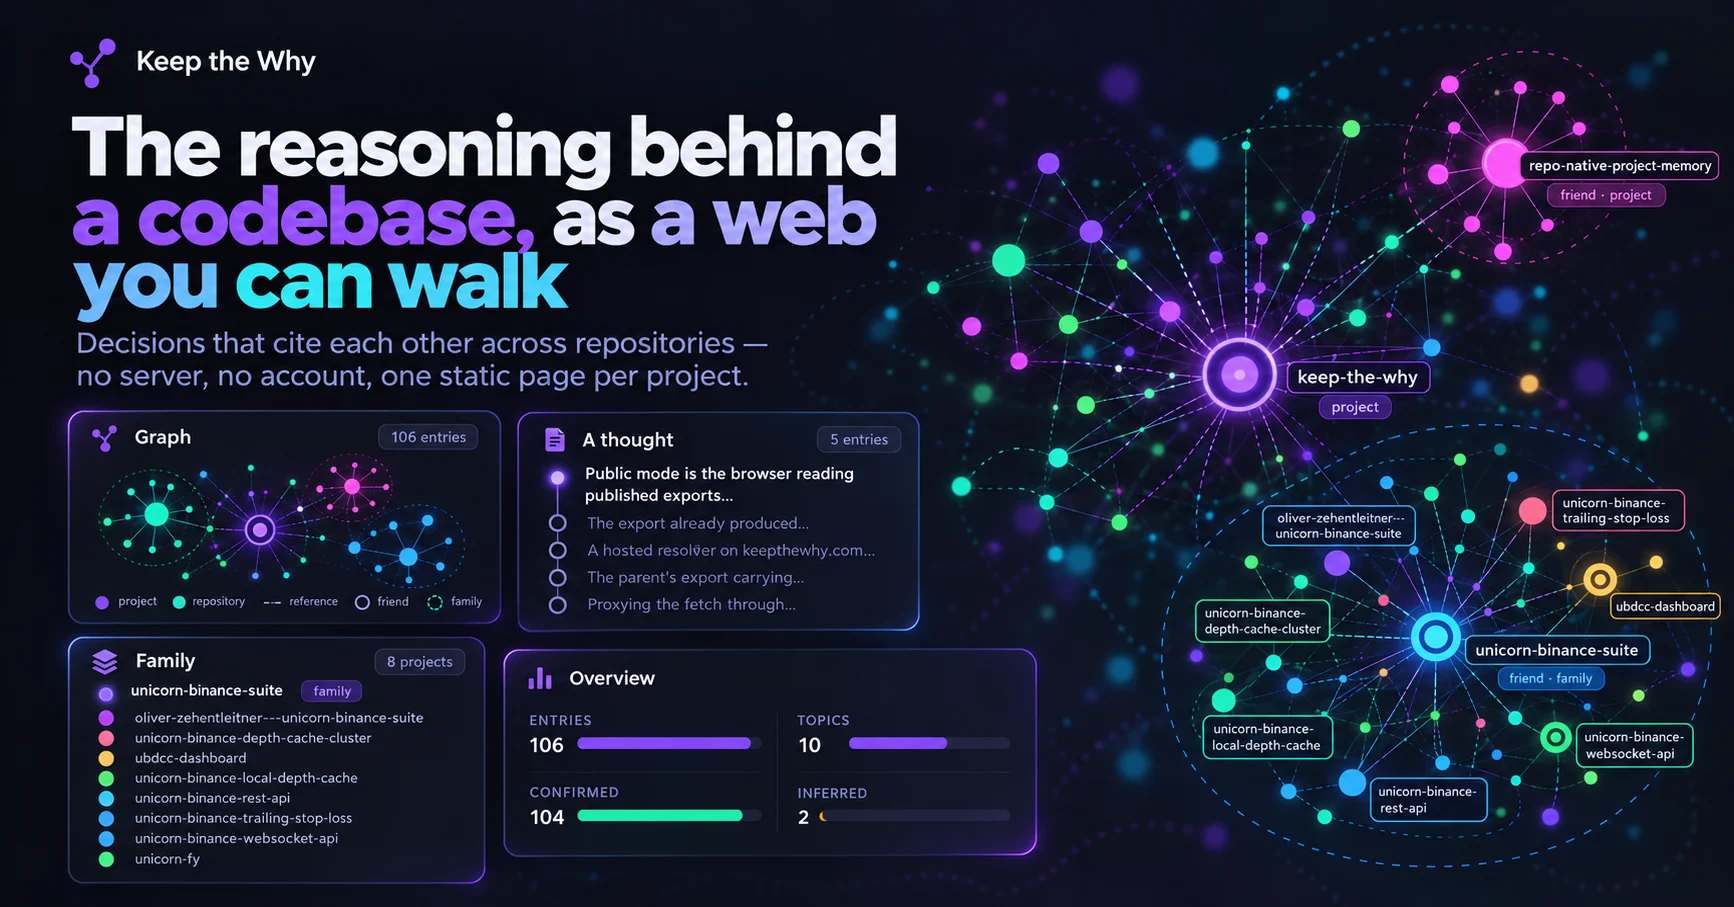
Open this before you read on: keepthewhy.com/dashboard/live/#graph Give it a few seconds to settle. Then come back. It looks like a knowledg...
Laya's README reports a raw ECE of 0.466 on the typed-decisions benchmark before temperature scaling.

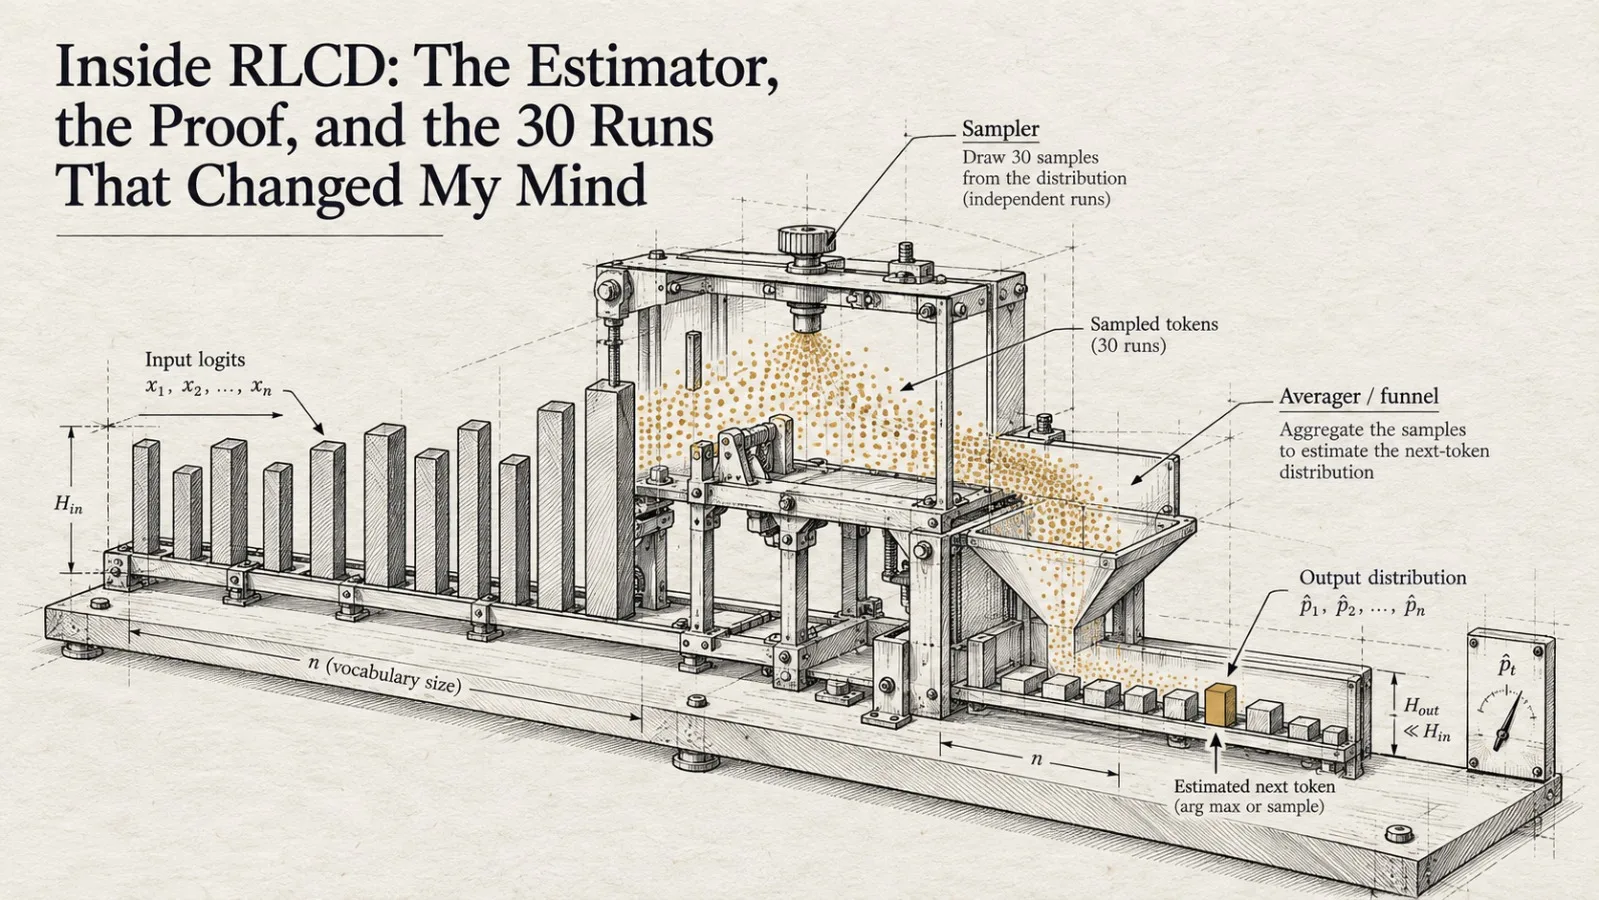
I went into this expecting the RL to be the interesting part. Laya's whole pitch is that a reinforcement-learning term turns noisy logits in...
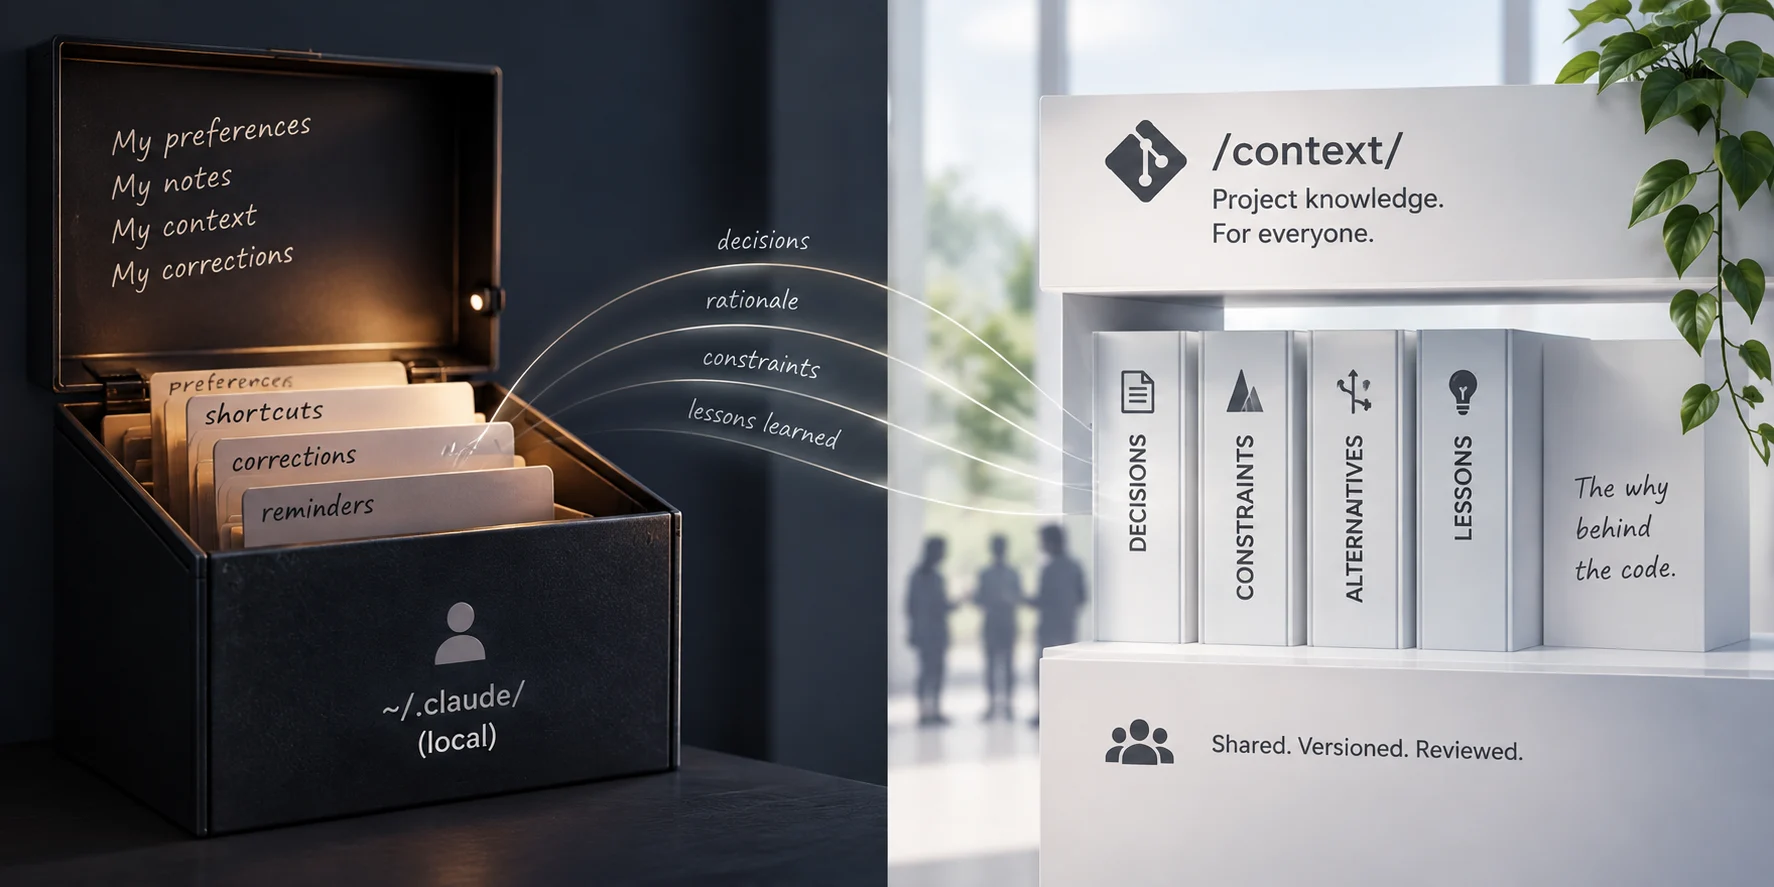
The most common complaint about coding agents is the same on every forum: a new session starts from nothing. The explanation you gave yester...
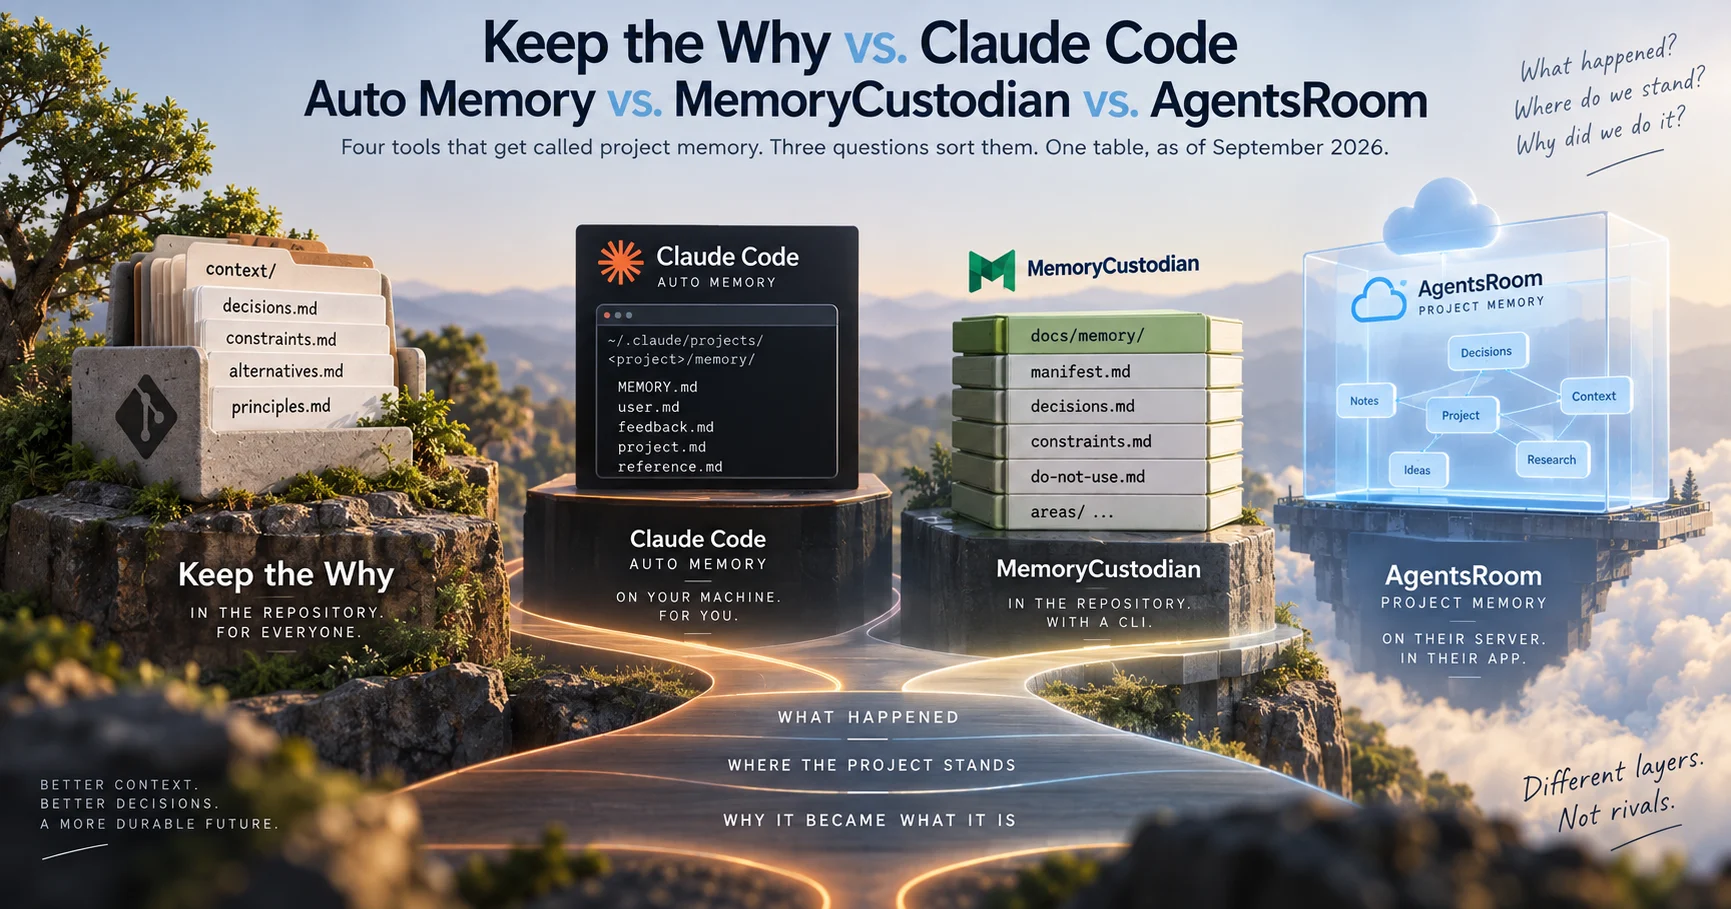
"Project memory for coding agents" now means at least four different things, and most comparisons put them in one list as if they competed. ...
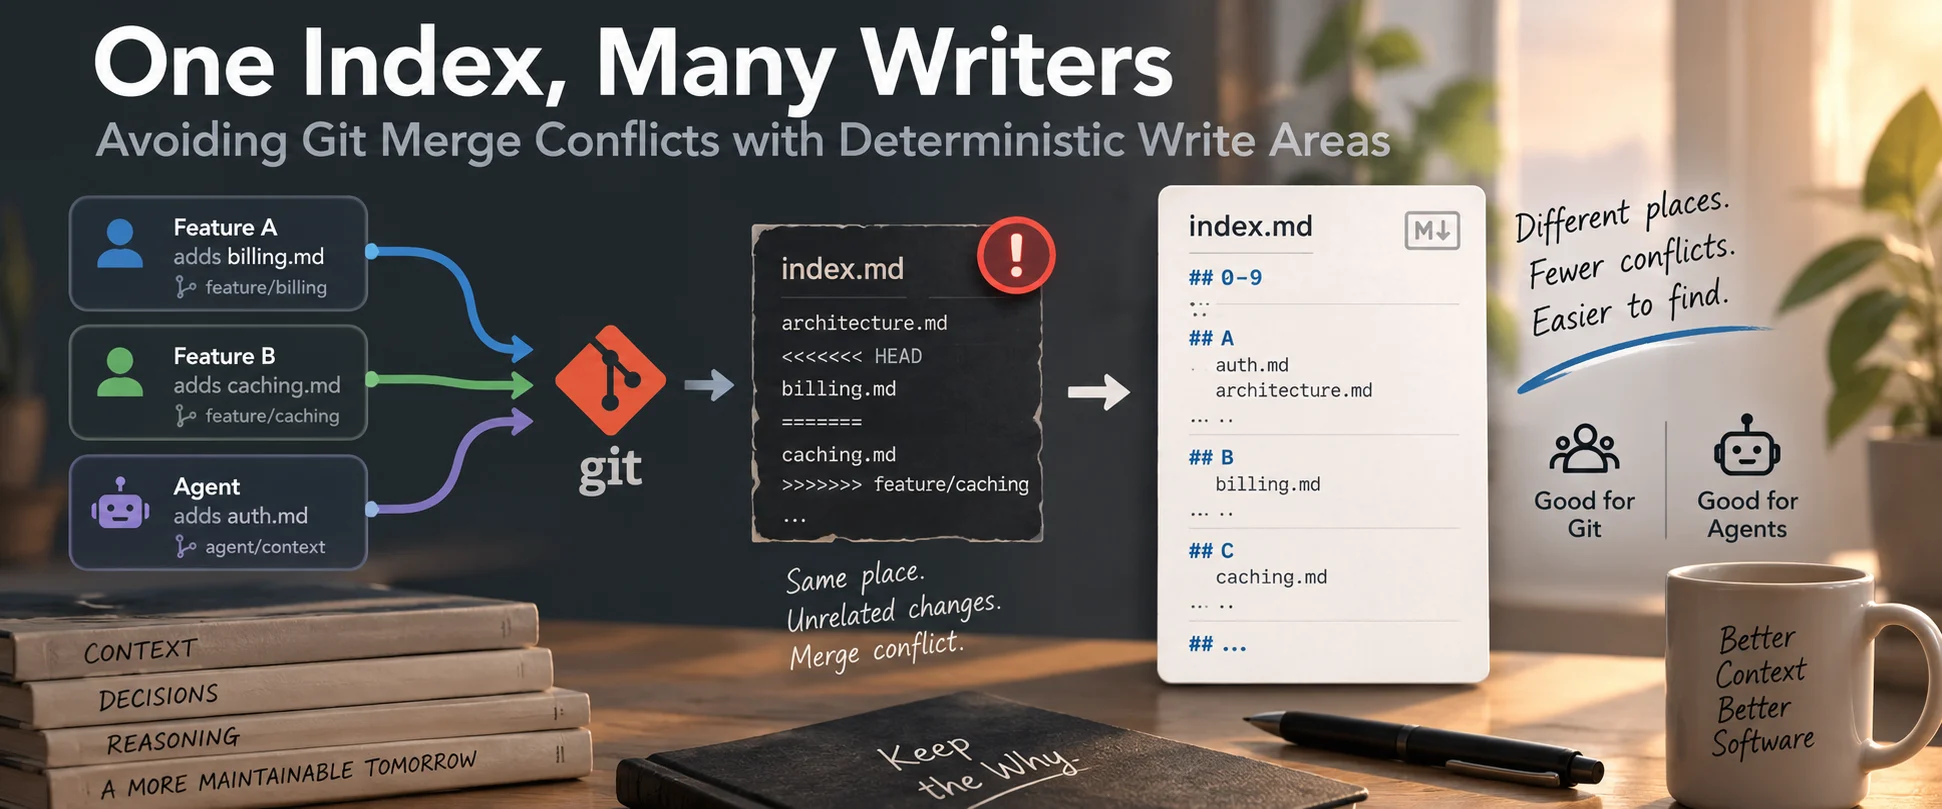
While working on Keep the Why, I ran into a very ordinary Git problem. There is one shared context/index.md. Developers and coding agents ca...
Every coding agent starts the day as a goldfish. It can read the code, reason about it, and still have no idea why any of it is the way it i...