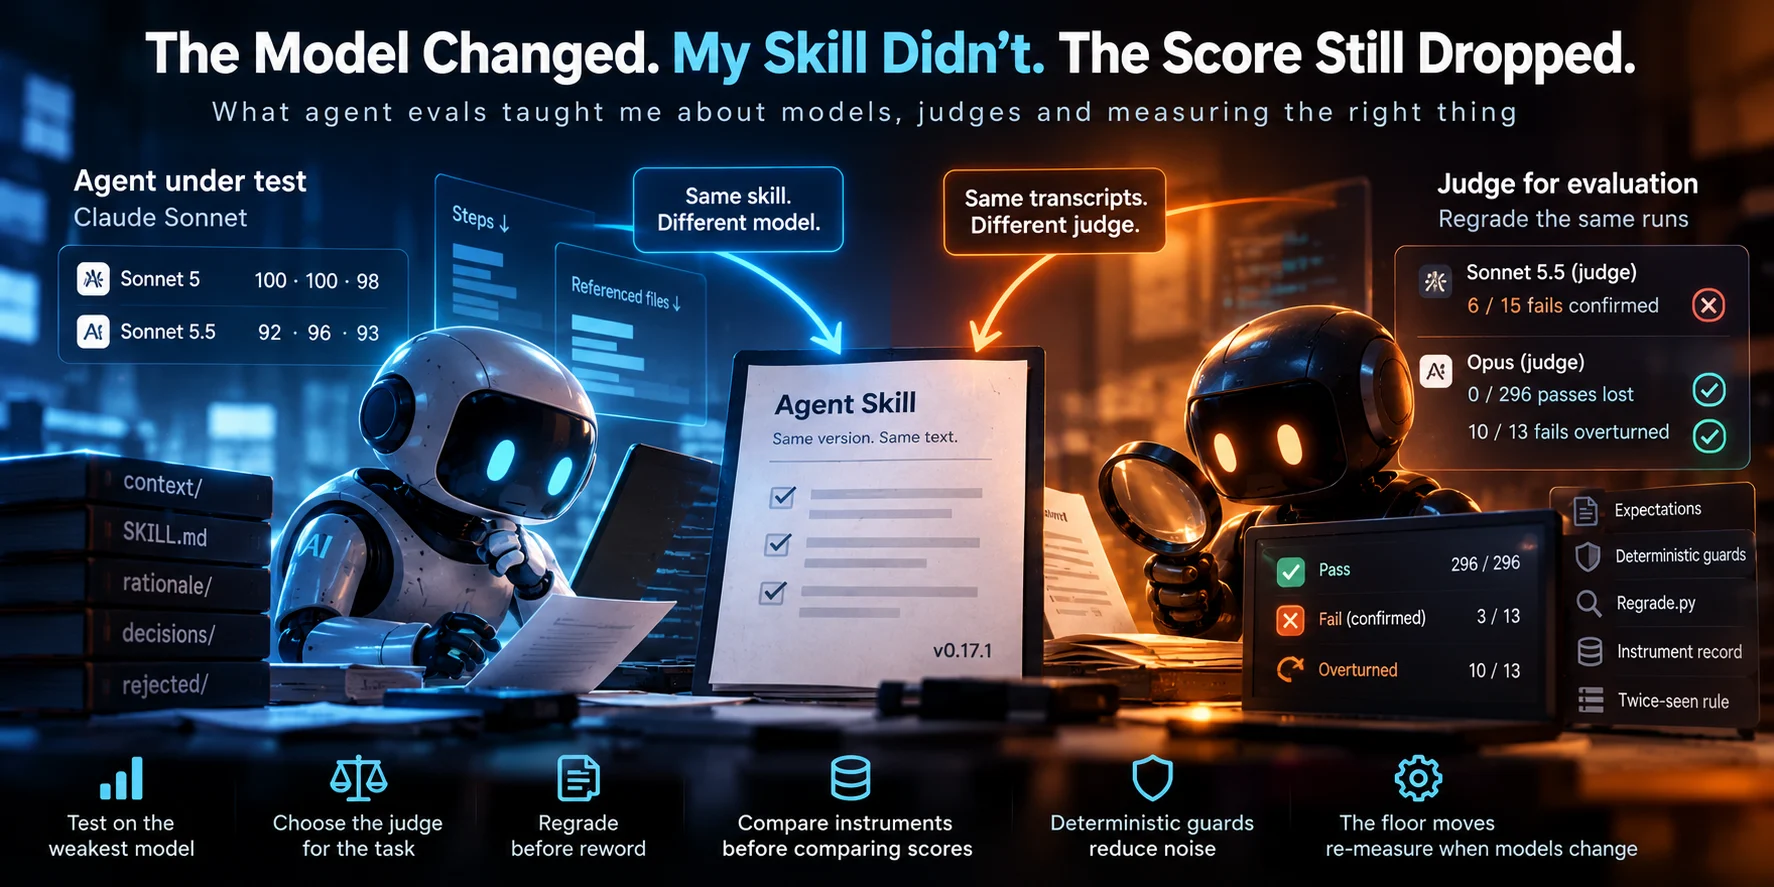
The Model Changed. My Skill Didn't. The Score Still Dropped.
My rule for evaluating an agent skill is deliberately asymmetric: Test the agent on the weakest model you intend to support. Choose the judg...
Oct 7, 2026
7 min
My rule for evaluating an agent skill is deliberately asymmetric: Test the agent on the weakest model you intend to support. Choose the judg...
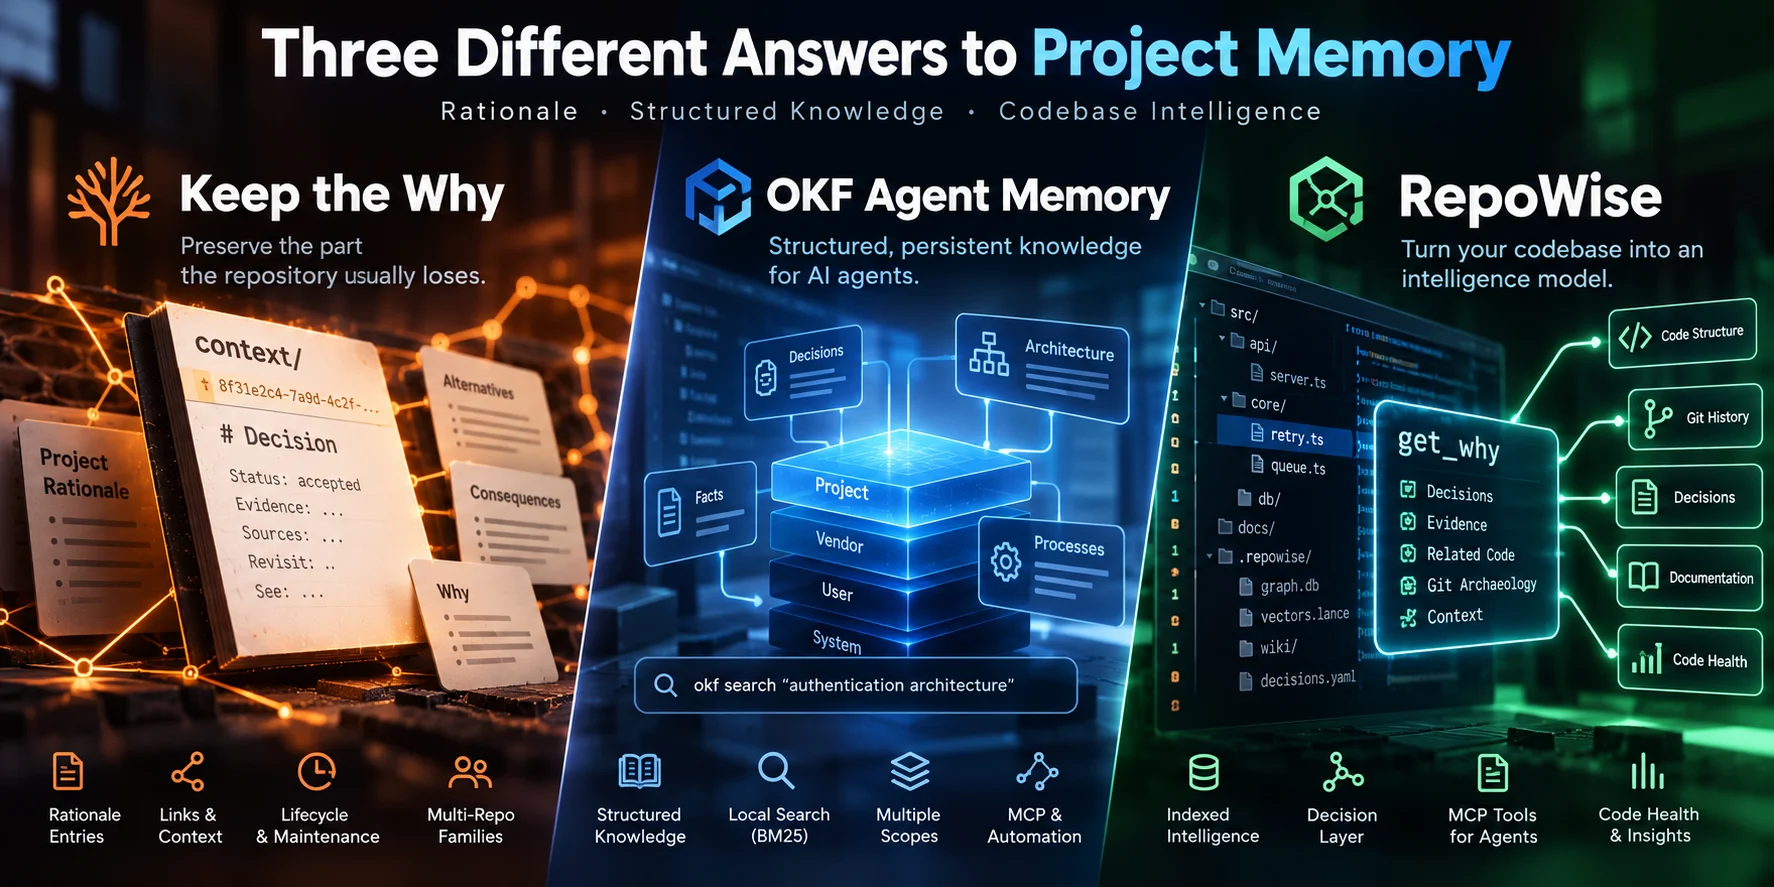
Three approaches to Git-native project memory for coding agents "Project memory for coding agents" is becoming a broad category. Three proje...
Give an autonomous coding agent a hundred-thousand-token context window, point it at a GitHub repository, and ask it to reproduce an ML base...

Part 2 explores the layers that separate demos from production AI systems. Learn how persistent memory differs from chat history, when to us...

Most developers think token optimization means shorter prompts. In 2026, the biggest costs come from bloated chat history, unused tool schem...

For two years, prompt engineering was the AI skill everyone wanted. LinkedIn courses, boot camps, six-figure job titles. Then something chan...