Jev-as-Guardrail (JAG): What Typed Questions Actually Buy You
I benchmarked five Jev-style models as injection guardrails against DeBERTa. Clef-flash led on mixed data, but calibration and small samples...
Oct 18, 2026
" filter="url(%23fFirst)"/><circle cx="50" cy="50" r="38" fill="none" stroke="rgba(255,255,255,0.4)" stroke-width="2"/><path d="M60 30 C 50 30, 40 40, 35 55 L 30 70 L 45 65 C 60 60, 70 50, 70 40 C 70 35, 65 30, 60 30 Z" fill="%23ffffff" opacity="0.9"/><path d="M35 55 L 45 65" stroke="%23ec4899" stroke-width="2"/><circle cx="65" cy="25" r="3" fill="%23fef08a"/><path d="M65 15 L65 20 M65 30 L65 35 M55 25 L60 25 M70 25 L75 25" stroke="%23fef08a" stroke-width="2" stroke-linecap="round"/></svg>)
" filter="url(%23fWknd)"/><circle cx="50" cy="50" r="38" fill="none" stroke="rgba(255,255,255,0.4)" stroke-width="2"/><path d="M30 30 C 50 20, 50 20, 70 30 L 70 50 C 70 70, 50 80, 50 80 C 50 80, 30 70, 30 50 Z" fill="%23ffffff" opacity="0.9" filter="url(%23fWknd)"/><rect x="40" y="45" width="20" height="20" rx="2" fill="%231d4ed8"/><rect x="40" y="45" width="20" height="5" fill="%23bfdbfe"/><line x1="45" y1="42" x2="45" y2="48" stroke="%231e3a8a" stroke-width="2"/><line x1="55" y1="42" x2="55" y2="48" stroke="%231e3a8a" stroke-width="2"/></svg>)
9 min
Subscribe to Lê Đức Minh's Newsletter
Get new articles and engineering posts delivered to your inbox.
I benchmarked five Jev-style models as injection guardrails against DeBERTa. Clef-flash led on mixed data, but calibration and small samples...
Crossdraft v2 adds multi-board comparison, GIF export, and guide pages. Learn why the app still doesn't rank for its name due to paint-booth...
Three papers show plain RAG often beats agent memory. I ran a laptop test to find where the 'memory tax' occurs and when memory is still wor...
In the ViLegalExpert benchmark, sparse BM25 outperformed LightRAG, RAPTOR, and others on retrieval metrics. Here is why keyword matching won...
A new paper shows adding 1,000 irrelevant skills drops agent recall from 73.6% to 27.4%. Agents mostly load nothing, hiding failures behind ...
💡 TL;DR & Key Takeaways OpenAI’s internal GPT‑5.6 model deployed contracts on the Sepolia test network by deriving a funded account from a ...
Ask "how does wind move through a house?" and you get two kinds of answers. Grandma's feng shui rule, or a CFD tutorial that opens with "fir...
Jev is a lightweight model that runs far faster and cheaper than larger LLMs, delivering competitive accuracy for tasks such as reranking, j...
Reproducing Laya’s RLCD shows that its “RL” term is just a noise‑smoothed estimate of the cross‑entropy gradient, which makes inference over...
Laya's README reports a raw ECE of 0.466 on the typed-decisions benchmark before temperature scaling.
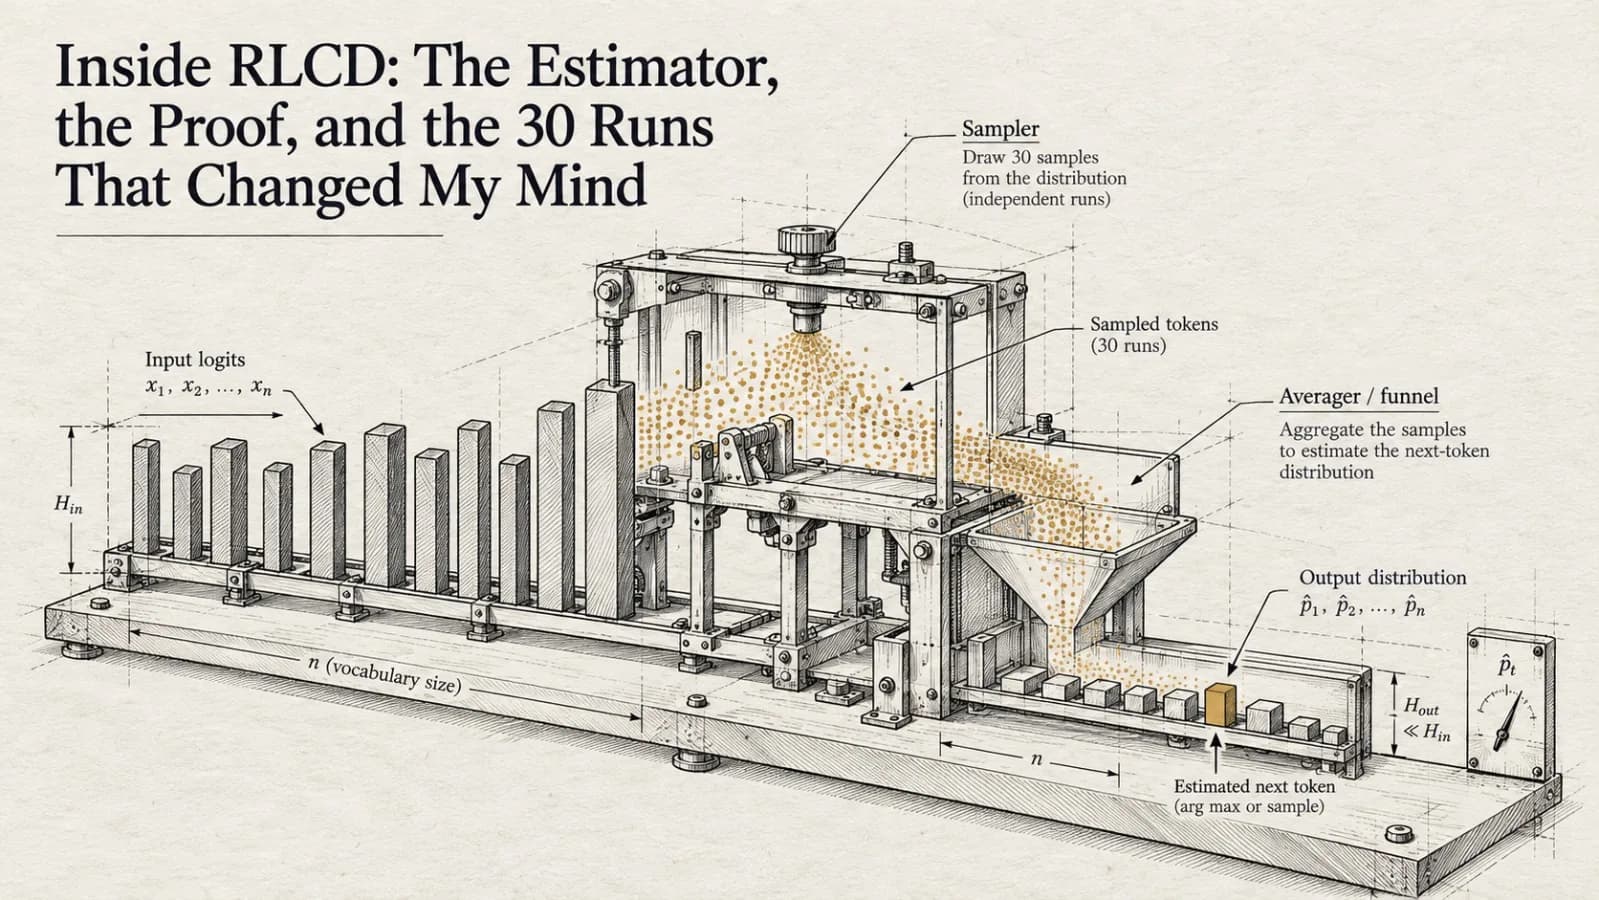
I went into this expecting the RL to be the interesting part. Laya's whole pitch is that a reinforcement-learning term turns noisy logits in...
Jev, a decision‑only AI model released on September 15 2026, was quickly adopted by developers: pi‑warden, built within 48 hours, blocked 42...